

[ad_1]
Evaluating the real-world applicability of huge language fashions (LLMs) is important to information their integration into sensible use circumstances. One key problem in assessing LLMs is their tendency to take advantage of mounted datasets throughout testing, resulting in inflated efficiency metrics. Static analysis frameworks usually fail to find out a mannequin’s means to adapt to suggestions or present clarifications, leading to evaluations that don’t mirror real-world situations. This hole in evaluation strategies necessitates a dynamic and iterative framework to check fashions below evolving circumstances.
Historically, analysis strategies like “LLM-as-a-Choose” depend on mounted datasets and static benchmarks to measure efficiency. Whereas these approaches usually correlate higher with human judgments than lexical matching methods, they undergo from biases, together with verbosity choice and inconsistent scoring throughout iterations. Additionally they fail to judge fashions in multi-turn interactions, the place adaptability and iterative enchancment are important. Consequently, these conventional strategies battle to seize a holistic understanding of an LLM’s capabilities.
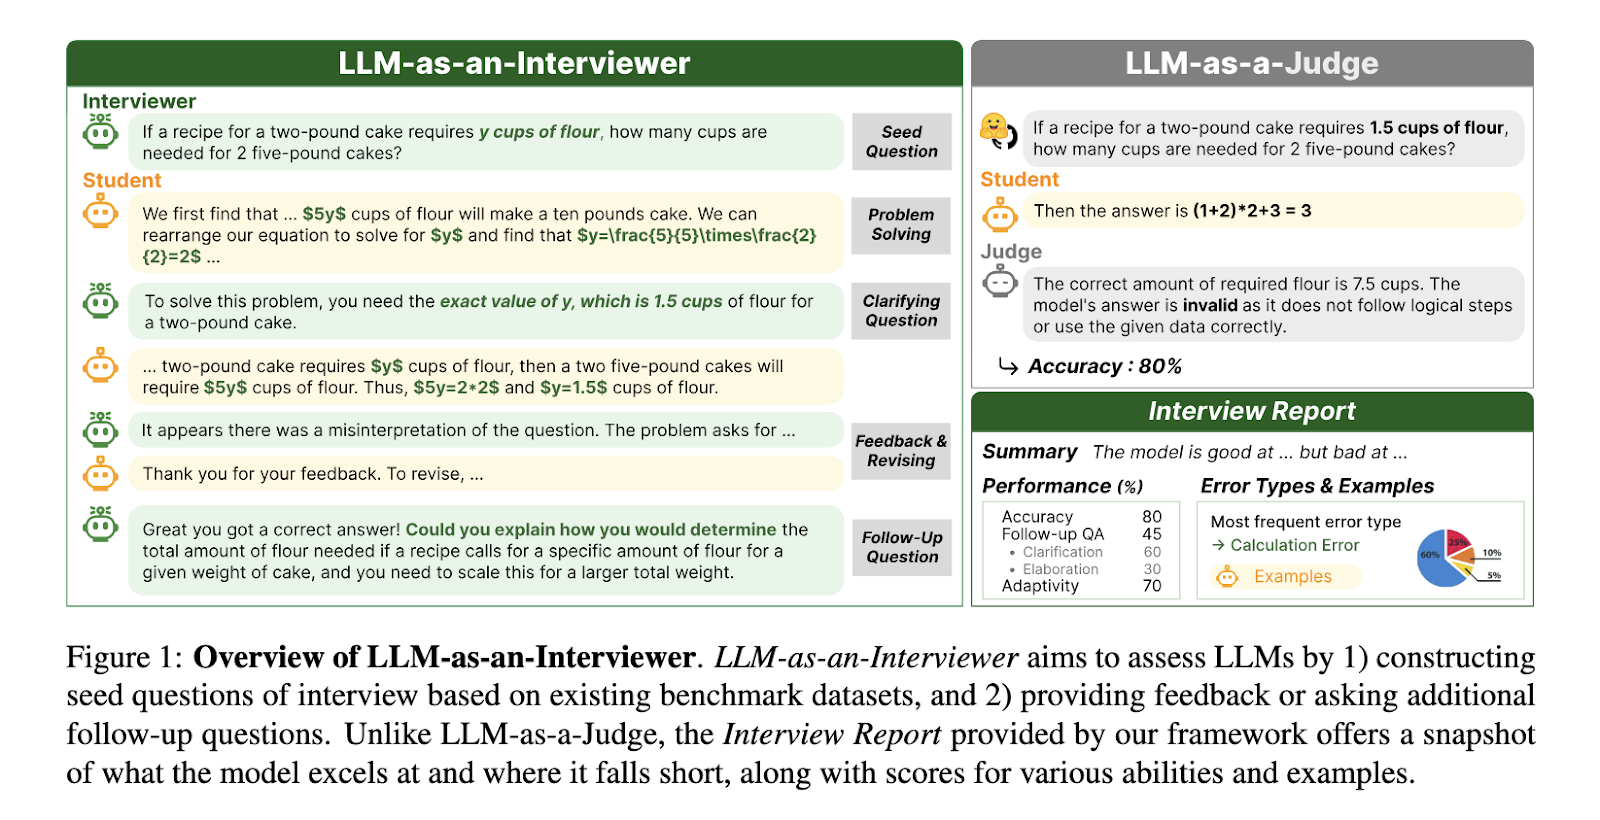
Researchers from KAIST, Stanford College, Carnegie Mellon College, and Contextual AI have launched LLM-AS-AN-INTERVIEWER, a novel framework for evaluating LLMs. This strategy mimics human interview processes by dynamically modifying datasets to generate tailor-made questions and offering suggestions on mannequin responses. The interviewer LLM adapts its questions based mostly on the evaluated mannequin’s efficiency, fostering an in depth and nuanced evaluation of its capabilities. Not like static strategies, this framework captures behaviors corresponding to response refinement and the power to handle further inquiries successfully.
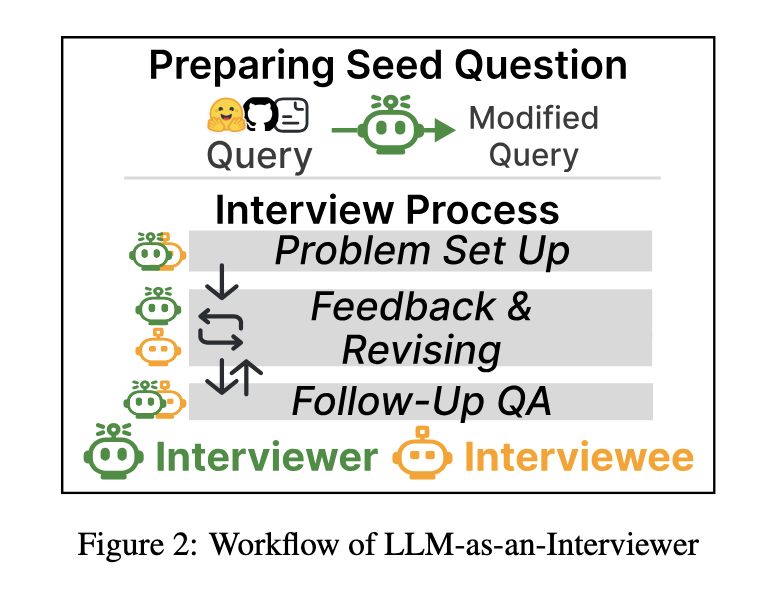
The framework operates in three levels: downside setup, suggestions and revision, and follow-up questioning. Initially, the interviewer creates numerous and difficult questions by modifying benchmark datasets. Throughout the interplay, it offers detailed suggestions on the mannequin’s responses and poses follow-up questions that check further facets of its reasoning or information. This iterative course of culminates in producing an “Interview Report,” which compiles efficiency metrics, error evaluation, and a complete abstract of the mannequin’s strengths and limitations. The report gives actionable insights into the mannequin’s real-world applicability and flexibility.
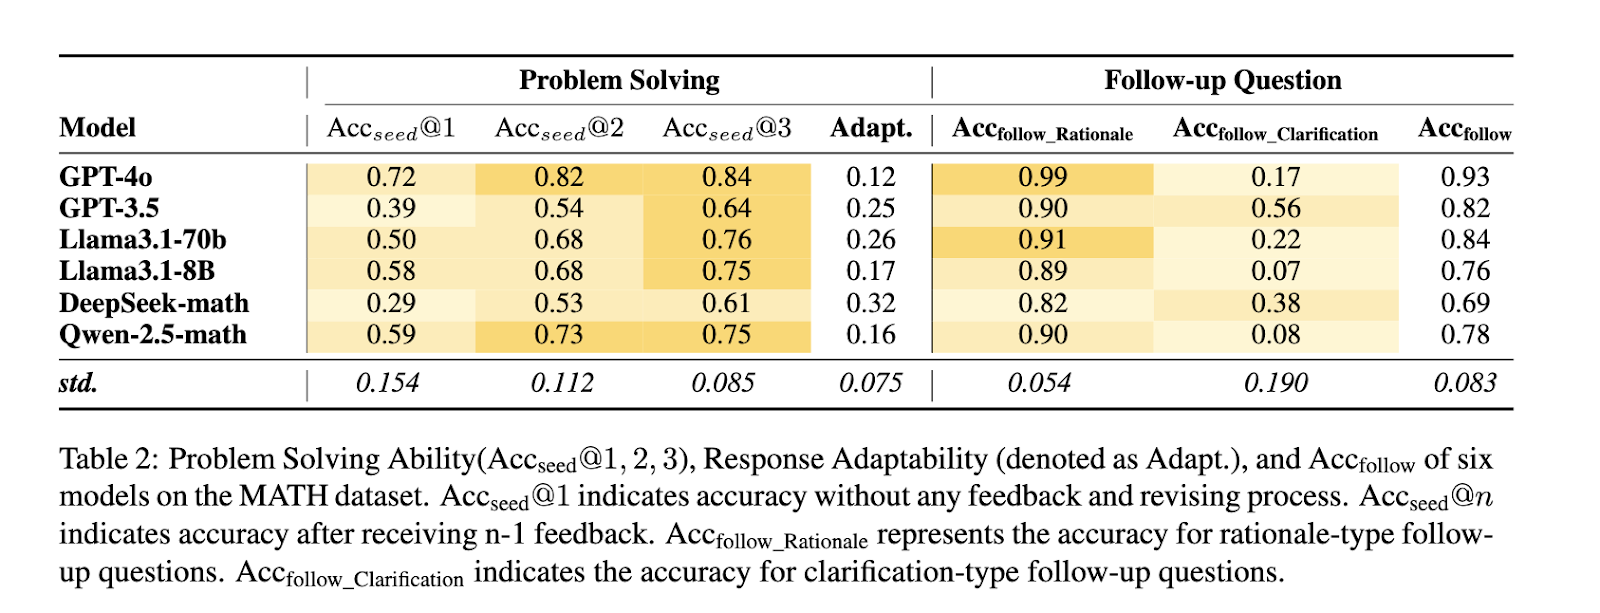
Experiments utilizing the MATH and DepthQA datasets show the framework’s efficacy. For MATH, which focuses on arithmetic reasoning, fashions like GPT-4o achieved % preliminary problem-solving accuracy of 72%. This accuracy elevated to 84% by way of iterative suggestions and interplay, highlighting the framework’s means to reinforce mannequin efficiency. Equally, DepthQA evaluations, which emphasize open-ended queries, revealed the effectiveness of follow-up questions in uncovering fashions’ information gaps and enhancing their responses. As an illustration, the adaptability metric for GPT-3.5 showcased a marked enchancment of 25% after iterative interactions, reflecting the mannequin’s means to refine solutions based mostly on suggestions.
The framework additionally addresses important biases prevalent in LLM evaluations. Verbosity bias, a bent to favor longer responses, diminishes as interactions progress, with a major drop in correlation between response size and scores. Additional, self-enhancement bias, the place fashions favor their responses throughout analysis, is minimized by way of dynamic interactions and comparative scoring. These changes guarantee constant and dependable analysis outcomes throughout a number of runs, with normal deviations reducing as suggestions iterations enhance.
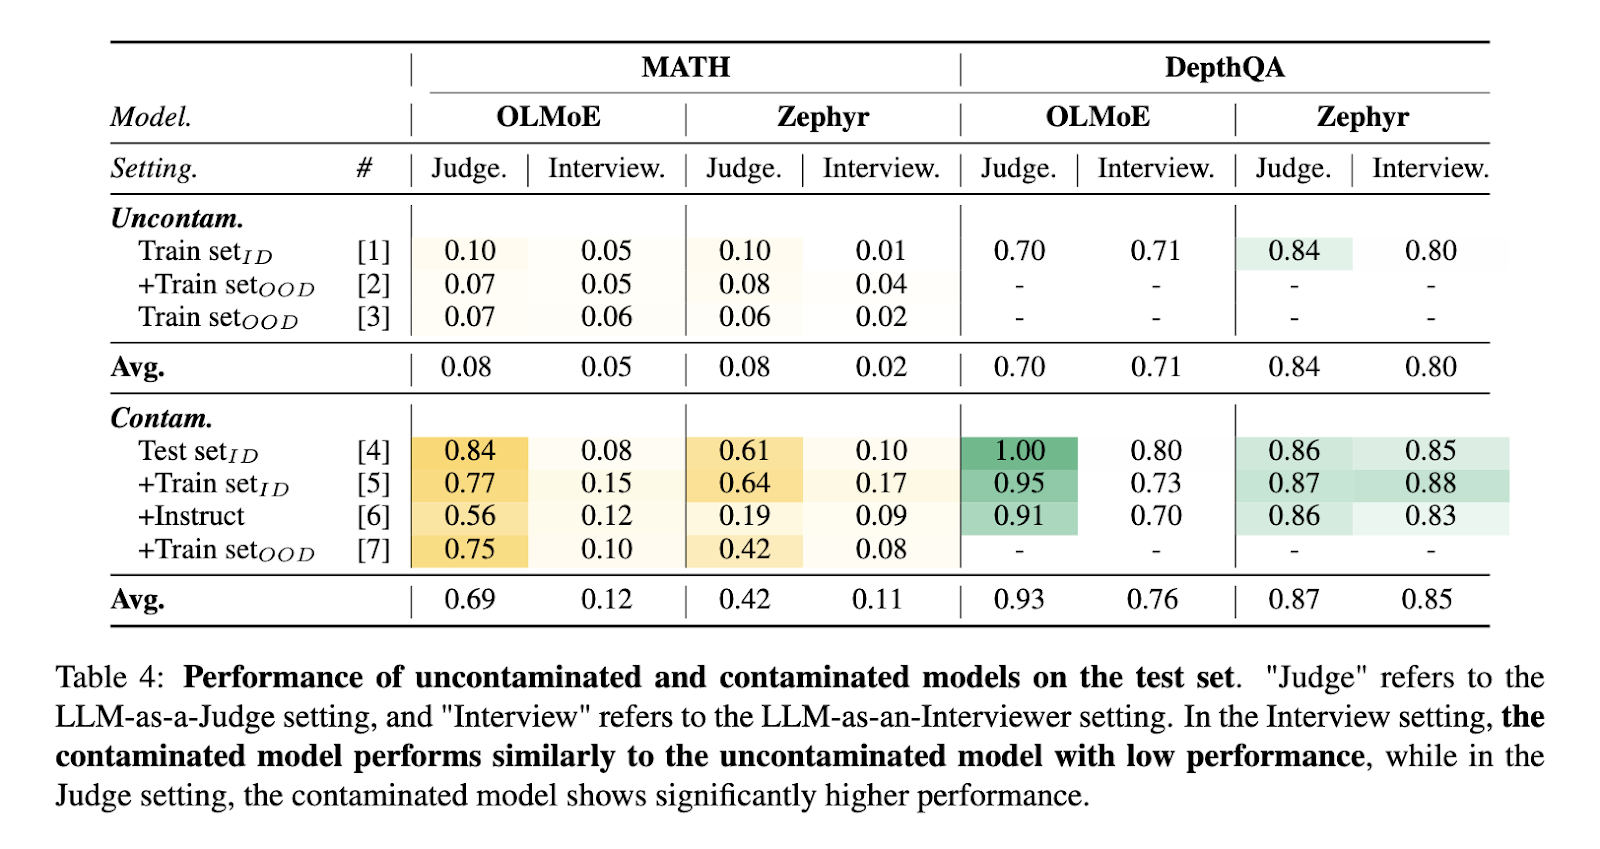
LLM-AS-AN-INTERVIEWER gives a strong resolution to information contamination, a serious LLM coaching and analysis concern. The framework mitigates contamination dangers by dynamically modifying benchmark questions and introducing novel follow-ups. For instance, fashions educated on contaminated datasets confirmed considerably increased efficiency in static settings however aligned extra intently with uncontaminated fashions when evaluated dynamically. This consequence underscores the framework’s means to differentiate between real mannequin capabilities and artifacts of coaching information overlap.
In conclusion, LLM-AS-AN-INTERVIEWER represents a paradigm shift in evaluating giant language fashions. Simulating human-like interactions and dynamically adapting to mannequin responses present a extra correct and nuanced understanding of their capabilities. The framework’s iterative nature highlights areas for enchancment and permits fashions to show their adaptability and real-world applicability. With its sturdy design and complete evaluation, this framework has the potential to set a brand new normal for LLM analysis, guaranteeing that future fashions are assessed with higher precision and relevance.
Try the Paper. All credit score for this analysis goes to the researchers of this venture. Additionally, don’t neglect to comply with us on Twitter and be part of our Telegram Channel and LinkedIn Group. Don’t Neglect to hitch our 60k+ ML SubReddit.
🚨 FREE UPCOMING AI WEBINAR (JAN 15, 2025): Enhance LLM Accuracy with Artificial Information and Analysis Intelligence–Be part of this webinar to realize actionable insights into boosting LLM mannequin efficiency and accuracy whereas safeguarding information privateness.
Nikhil is an intern advisor at Marktechpost. He’s pursuing an built-in twin diploma in Supplies on the Indian Institute of Know-how, Kharagpur. Nikhil is an AI/ML fanatic who’s all the time researching purposes in fields like biomaterials and biomedical science. With a powerful background in Materials Science, he’s exploring new developments and creating alternatives to contribute.
[ad_2]
Source link


