

[ad_1]
Machines study to attach photos and textual content by coaching on giant datasets, the place extra information helps fashions acknowledge patterns and enhance accuracy. Imaginative and prescient-language fashions (VLMs) depend on these datasets to carry out duties like picture captioning and visible query answering. The query is whether or not growing datasets to 100 billion examples dramatically improves accuracy, cultural variety, and assist for low-resource languages. Scaling past 10 billion has slowed down, and doubts are raised about whether or not there can be additional advantages. With such monumental information come high quality management issues, bias, and computational constraints.
At the moment, vision-language fashions depend upon large datasets comparable to Conceptual Captions and LAION, with thousands and thousands to billions of image-text pairs. These datasets allow zero-shot classification and picture captioning, however their development has slowed to round 10 billion pairs. This constraint minimizes the prospect of additional refining mannequin accuracy, inclusivity, and multilingual comprehension. Present approaches are primarily based on web-crawled information, which poses points like low-quality samples, linguistic biases, and underrepresentation of multiculturalism. The effectivity of additional scaling is questionable past this level, bringing into query the power of elevated dataset dimension alone to provide substantial enhancements.
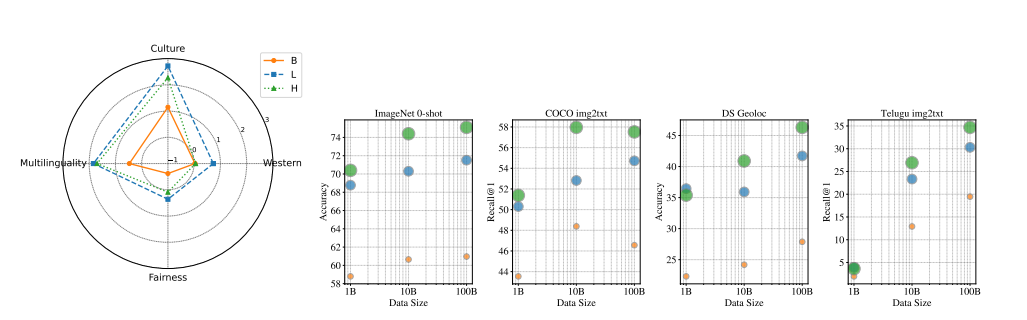
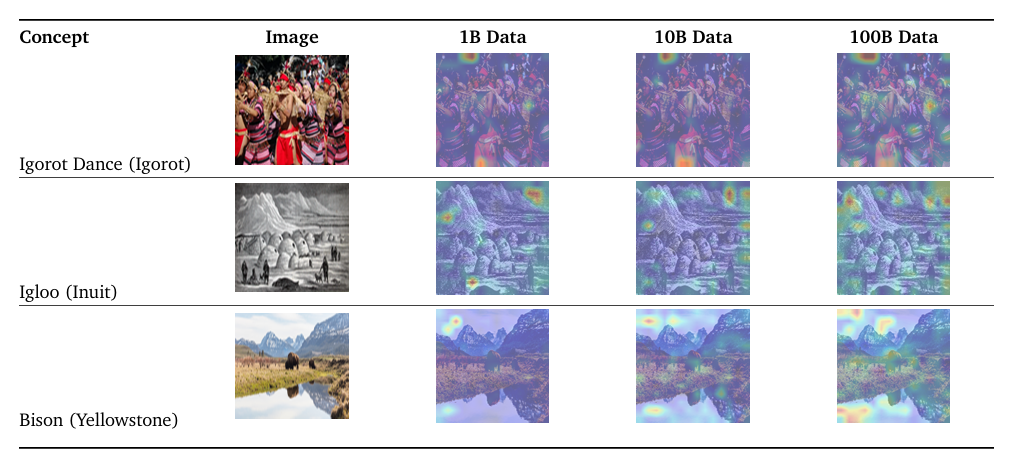
To mitigate limitations in cultural variety and multilinguality in vision-language fashions, researchers from Google Deepmind proposed WebLI-100B, a dataset containing 100 billion image-text pairs, which is ten instances bigger than earlier datasets. This dataset captures uncommon cultural ideas and improves mannequin efficiency in less-explored areas like low-resource languages and various representations. In contrast to prior datasets, WebLI-100B focuses on scaling information as a substitute of counting on heavy filtering, which frequently removes essential cultural particulars. The framework includes pre-training fashions on totally different subsets of the WebLI-100B dataset (1B, 10B, and 100B) to research the influence of knowledge scaling. Fashions educated on the total dataset carried out higher in cultural and multilingual duties than these educated on smaller datasets, even when utilizing the identical computational sources. As an alternative of aggressive filtering, the dataset maintains a broad illustration of languages and cultural parts, making it extra inclusive.
Researchers created a quality-filtered 5B dataset and a language-rebalanced model to upsample low-resource languages. Utilizing the SigLIP mannequin, they educated on totally different dataset sizes (1B, 10B, and 100B) with ViT architectures and a contrastive studying method. The analysis lined zero-shot and few-shot classification duties comparable to ImageNet, CIFAR–100, and COCO Captions, cultural variety benchmarks like Greenback Avenue and GeoDE, and multilingual retrieval utilizing Crossmodal-3600. Outcomes indicated that growing the dataset dimension from 10B to 100B had minimal influence on Western-centric benchmarks however led to enhancements in cultural variety duties and low-resource language retrieval. Bias evaluation revealed persistent gender-related illustration and affiliation biases regardless of efficiency disparity enhancing alongside variety good points. Lastly, researchers assessed mannequin transferability to generative duties utilizing PaliGemma, testing frozen and unfrozen settings for downstream vision-language purposes.
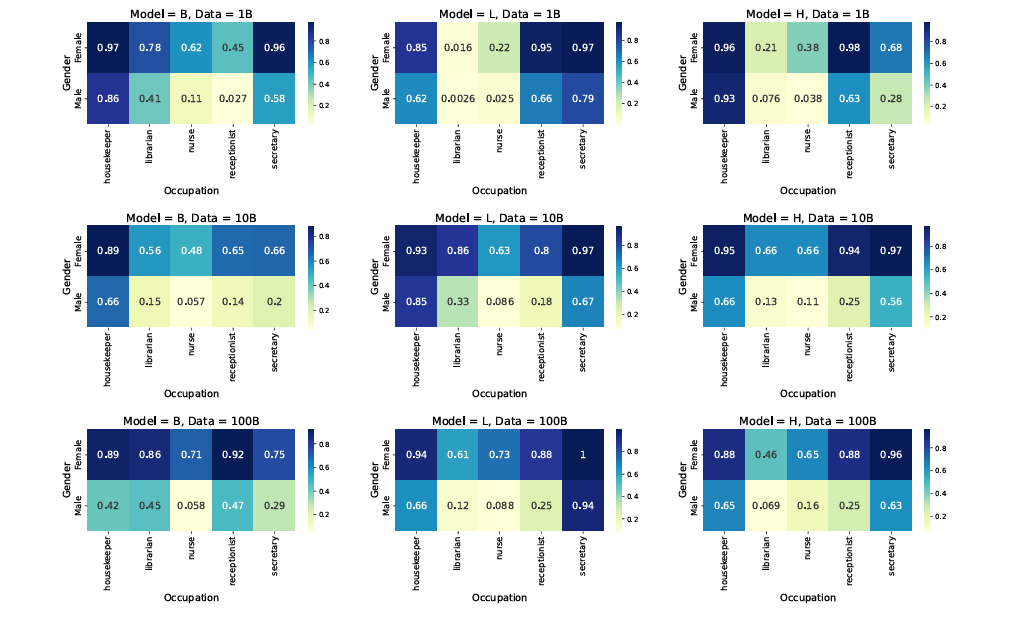
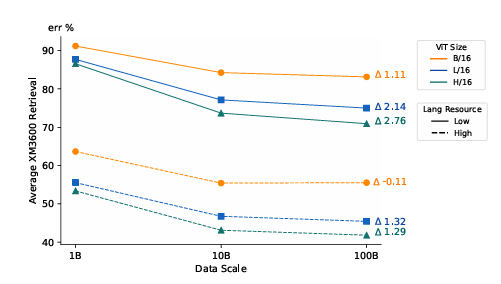
In conclusion, scaling vision-language pre-training datasets to 100 billion image-text pairs improved inclusivity by enhancing cultural variety and multilinguality, and decreasing efficiency disparity throughout subgroups, though conventional benchmarks confirmed restricted good points. Whereas high quality filters like CLIP improved efficiency on normal duties, they usually lowered information variety. This work can function a reference for future analysis by stimulating the creation of filtering algorithms that keep variety and coaching methods that promote inclusivity with no need additional information and informing future enhancements on balancing efficiency, variety, and equity in vision-language fashions.
Try the Paper. All credit score for this analysis goes to the researchers of this challenge. Additionally, be at liberty to comply with us on Twitter and don’t overlook to hitch our 75k+ ML SubReddit.
🚨 Really useful Open-Supply AI Platform: ‘IntellAgent is a An Open-Supply Multi-Agent Framework to Consider Advanced Conversational AI System’ (Promoted)
Divyesh is a consulting intern at Marktechpost. He’s pursuing a BTech in Agricultural and Meals Engineering from the Indian Institute of Know-how, Kharagpur. He’s a Information Science and Machine studying fanatic who needs to combine these main applied sciences into the agricultural area and remedy challenges.
[ad_2]
Source link


