

[ad_1]
The present research examines how effectively LLMs align with fascinating attributes, resembling helpfulness, harmlessness, factual accuracy, and creativity. The first focus is on a two-stage course of that includes studying a reward mannequin from human preferences after which aligning the language mannequin to maximise this reward. It addresses two key points:
Bettering alignment by contemplating completely different transformations of the realized reward.
Successfully combining a number of reward fashions when aligning language fashions to varied attributes.
Nevertheless, the problem lies within the want for a exactly outlined aim for alignment, which ends up in exploring varied transformation and aggregation strategies with no clear tenet.
Researchers from the College of Chicago, Google Analysis, Google DeepMind, and Stanford College point out the issue of aligning language fashions to human preferences by studying a reward mannequin from choice knowledge and updating the language mannequin, proposing a change approach for rewards and the mixture of a number of reward fashions. The derived transformation emphasizes enhancing poorly performing outputs and allows principled aggregation of rewards, resulting in substantial enhancements in aligning language fashions to be useful and innocent.

Varied methods deal with reward hacking in Reinforcement Studying from Human Suggestions (RLHF), together with reward mannequin averaging, constrained optimization, and iterative human choice assortment. By proposing a complementary methodology, the research explores aligning language fashions to a number of targets, with widespread approaches involving weighted sum mixtures of particular person reward fashions. The transformation approach offered applies to alignment methods maximizing anticipated utility. Whereas some alignment strategies use choice labels straight, rankings are computed from an combination when aligning to a number of properties. It addresses the necessity for a bounded utility operate.
The analysis mentions a change approach for aligning language fashions to human preferences by studying a reward mannequin from choice knowledge and updating the language mannequin. The researchers use a probabilistic interpretation of the alignment process to determine a pure selection for transformation for rewards realized from Bradley-Terry choice fashions. The derived transformation emphasizes enhancing poorly performing outputs and mitigates underfitting and reward hacking. The research additionally explores the mixture of a number of reward fashions and allows principled aggregation of rewards by linking summation to logical conjunction. Experiments are performed, aligning language fashions to be useful and innocent utilizing RLHF and displaying substantial enhancements over the baseline strategy.
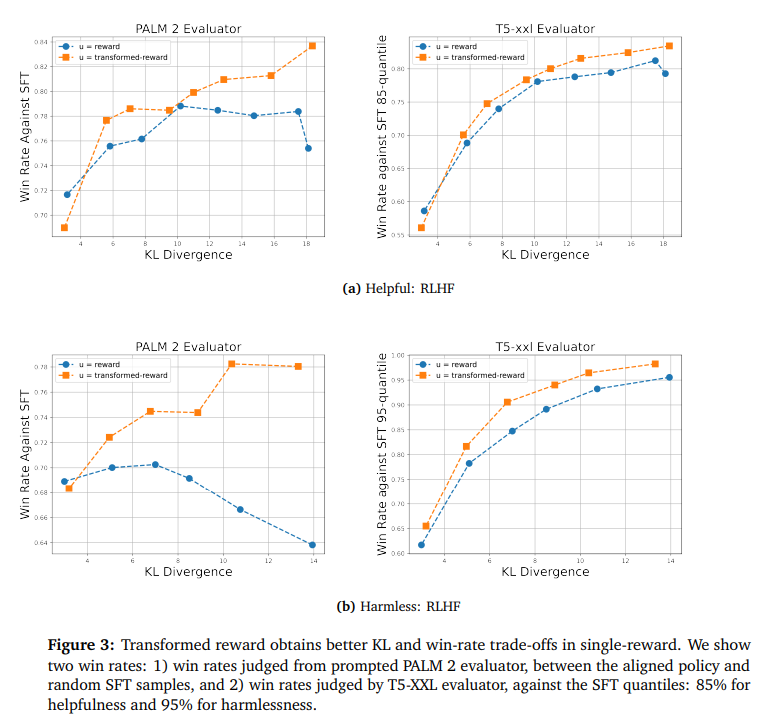
In comparison with the baseline strategy, the strategy demonstrates substantial enhancements in aligning language fashions to be useful and innocent utilizing RLHF. The transformation approach for rewards and mixing a number of reward fashions present promising ends in aligning language fashions to human preferences. Summing the reworked rewards corresponds higher to logical AND, resulting in extra balanced reward distributions and outperforming the baseline reward methodology. The transformed-aligned mannequin outperforms the baseline in best-of-k and low-KL instances, whereas in high-KL instances, the transformed-reward dramatically outperforms the raw-reward baseline. The experiments performed within the research present proof of the effectiveness of the talked about strategies in enhancing the alignment of language fashions to human preferences.
In conclusion, The analysis proposes a way for aligning language fashions to human preferences, specializing in enhancing poorly performing outputs and enabling principled aggregation of rewards. The transformation for rewards realized from Bradley-Terry choice fashions has two important properties: it improves poorly performing outputs and permits for principled reward aggregation. Experiments performed utilizing RLHF reveal substantial enhancements over the baseline strategy, proving the effectiveness of the proposed strategies. It emphasizes the significance of contemplating each helpfulness and harmlessness in aligning language fashions, and the developed strategies present a promising strategy to attaining this alignment by combining a number of reward fashions and utilizing logical conjunction in reward aggregation.
Try the Paper. All credit score for this analysis goes to the researchers of this undertaking. Additionally, don’t overlook to observe us on Twitter and Google Information. Be a part of our 36k+ ML SubReddit, 41k+ Fb Neighborhood, Discord Channel, and LinkedIn Group.
In case you like our work, you’ll love our publication..
Don’t Neglect to affix our Telegram Channel
Sana Hassan, a consulting intern at Marktechpost and dual-degree scholar at IIT Madras, is keen about making use of know-how and AI to deal with real-world challenges. With a eager curiosity in fixing sensible issues, he brings a recent perspective to the intersection of AI and real-life options.
[ad_2]
Source link


