

[ad_1]
whether or not GenAI is simply hype or exterior noise. I additionally thought this was hype, and I might sit this one out till the mud cleared. Oh, boy, was I mistaken. GenAI has real-world functions. It additionally generates income for corporations, so we count on corporations to take a position closely in analysis. Each time a expertise disrupts one thing, the method usually strikes by means of the next phases: denial, anger, and acceptance. The identical factor occurred when computer systems had been launched. If we work within the software program or {hardware} subject, we would want to make use of GenAI sooner or later.
On this article, I cowl find out how to energy your utility with massive Language Fashions (LLMs) and focus on the challenges I confronted whereas establishing LLMs. Let’s get began.
1. Begin by defining your use case clearly
Earlier than leaping onto LLM, we should always ask ourselves some questions
a. What downside will my LLM remedy? b. Can my utility do with out LLMc. Do I’ve sufficient sources and compute energy to develop and deploy this utility?
Slim down your use case and doc it. In my case, I used to be engaged on an information platform as a service. We had tons of knowledge on wikis, Slack, staff channels, and so on. We wished a chatbot to learn this data and reply questions on our behalf. The chatbot would reply buyer questions and requests on our behalf, and if clients had been nonetheless sad, they’d be routed to an Engineer.
2. Select your mannequin

You might have two choices: Prepare your mannequin from scratch or use a pre-trained mannequin and construct on high of it. The latter would work typically until you may have a selected use case. Coaching your mannequin from scratch would require huge computing energy, important engineering efforts, and prices, amongst different issues. Now, the subsequent query is, which pre-trained mannequin ought to I select? You possibly can choose a mannequin based mostly in your use case. 1B parameter mannequin has primary data and sample matching. Use instances may be restaurant opinions. The 10B parameter mannequin has wonderful data and might comply with directions like a meals order chatbot. A 100B+ parameters mannequin has wealthy world data and sophisticated reasoning. This can be utilized as a brainstorming companion. There are various fashions out there, resembling Llama and ChatGPT. After you have a mannequin in place, you’ll be able to increase on the mannequin.
3. Improve the mannequin as per your information
After you have a mannequin in place, you’ll be able to increase on the mannequin. The LLM mannequin is educated on usually out there information. We need to prepare it on our information. Our mannequin wants extra context to supply solutions. Let’s assume we need to construct a restaurant chatbot that solutions buyer questions. The mannequin doesn’t know data explicit to your restaurant. So, we need to present the mannequin some context. There are various methods we are able to obtain this. Let’s dive into a few of them.
Immediate Engineering
Immediate engineering entails augmenting the enter immediate with extra context throughout inference time. You present context in your enter quote itself. That is the best to do and has no enhancements. However this comes with its disadvantages. You can’t give a big context contained in the immediate. There’s a restrict to the context immediate. Additionally, you can not count on the consumer to at all times present full context. The context is perhaps intensive. This can be a fast and simple answer, but it surely has a number of limitations. Here’s a pattern immediate engineering.
“Classify this reviewI love the movieSentiment: Constructive
Classify this reviewI hated the film.Sentiment: Adverse
Classify the movieThe ending was thrilling”
Bolstered Studying With Human Suggestions (RLHF)

RLHF is among the most-used strategies for integrating LLM into an utility. You present some contextual information for the mannequin to be taught from. Right here is the circulation it follows: The mannequin takes an motion from the motion house and observes the state change within the setting on account of that motion. The reward mannequin generated a reward rating based mostly on the output. The mannequin updates its weight accordingly to maximise the reward and learns iteratively. For example, in LLM, motion is the subsequent phrase that the LLM generates, and the motion house is the dictionary of all doable phrases and vocabulary. The setting is the textual content context; the State is the present textual content within the context window.
The above clarification is extra like a textbook clarification. Let’s take a look at a real-life instance. You need your chatbot to reply questions concerning your wiki paperwork. Now, you select a pre-trained mannequin like ChatGPT. Your wikis will probably be your context information. You possibly can leverage the langchain library to carry out RAG. You possibly can Here’s a pattern code in Python
from langchain.document_loaders import WikipediaLoader
from langchain.text_splitter import RecursiveCharacterTextSplitter
from langchain.embeddings import OpenAIEmbeddings
from langchain.vectorstores import FAISS
from langchain.chat_models import ChatOpenAI
from langchain.chains import RetrievalQA
import os
# Set your OpenAI API key
os.environ[“OPENAI_API_KEY”] = “your-openai-key-here”
# Step 1: Load Wikipedia paperwork
question = “Alan Turing”
wiki_loader = WikipediaLoader(question=question, load_max_docs=3)
wiki_docs = wiki_loader.load()
# Step 2: Break up the textual content into manageable chunks
splitter = RecursiveCharacterTextSplitter(chunk_size=500, chunk_overlap=100)
split_docs = splitter.split_documents(wiki_docs)
# Step 3: Embed the chunks into vectors
embeddings = OpenAIEmbeddings()
vector_store = FAISS.from_documents(split_docs, embeddings)
# Step 4: Create a retriever
retriever = vector_store.as_retriever(search_type=”similarity”, search_kwargs={“okay”: 3})
# Step 5: Create a RetrievalQA chain
llm = ChatOpenAI(temperature=0, model_name=”gpt-3.5-turbo”)
qa_chain = RetrievalQA.from_chain_type(
llm=llm,
chain_type=”stuff”, # You can too attempt “map_reduce” or “refine”
retriever=retriever,
return_source_documents=True,
)
# Step 6: Ask a query
query = “What did Alan Turing contribute to laptop science?”
response = qa_chain(query)
# Print the reply
print(“Reply:”, response[“result”])
print(“n— Sources —“)
for doc in response[“source_documents”]:
print(doc.metadata)
4. Consider your mannequin
Now, you may have added RAG to your mannequin. How do you test in case your mannequin is behaving appropriately? This isn’t a code the place you give some enter parameters and obtain a hard and fast output, which you’ll be able to take a look at in opposition to. Since it is a language-based communication, there may be a number of right solutions. However what you’ll be able to know for certain is whether or not the reply is wrong. There are various metrics you’ll be able to take a look at your mannequin in opposition to.
Consider manually
You possibly can frequently consider your mannequin manually. For example, we had built-in a Slack chatbot that was enhanced with RAG utilizing our wikis and Jira. As soon as we added the chatbot to the Slack channel, we initially shadowed its responses. The purchasers couldn’t view the responses. As soon as we gained confidence, we made the chatbot publicly seen to the purchasers. We evaluated its response manually. However it is a fast and imprecise method. You can’t achieve confidence from such guide testing. So, the answer is to check in opposition to some benchmark, resembling ROUGE.
Consider with ROUGE rating.
ROUGE metrics are used for textual content summarization. Rouge metrics evaluate the generated abstract with reference summaries utilizing totally different ROUGE metrics. Rouge metrics consider the mannequin utilizing recall, precision, and F1 scores. ROUGE metrics are available in numerous sorts, and poor completion can nonetheless end in rating; therefore, we check with totally different ROUGE metrics. For some context, a unigram is a single phrase; a bigram is 2 phrases; and an n-gram is N phrases.
ROUGE-1 Recall = Unigram matches/Unigram in referenceROUGE-1 Precision = Unigram matches/Unigram in generated outputROUGE-1 F1 = 2 * (Recall * Precision / (Recall + Precision))ROUGE-2 Recall = Bigram matches/bigram referenceROUGE-2 Precision = Bigram matches / Bigram in generated outputROUGE-2 F1 = 2 * (Recall * Precision / (Recall + Precision))ROUGE-L Recall = Longest widespread subsequence/Unigram in referenceROUGE-L Precision = Longest widespread subsequence/Unigram in outputROUGE-L F1 = 2 * (Recall * Precision / (Recall + Precision))
For instance,
Reference: “It’s chilly exterior.”Generated output: “It is extremely chilly exterior.”
ROUGE-1 Recall = 4/4 = 1.0ROUGE-1 Precision = 4/5 = 0.8ROUGE-1 F1 = 2 * 0.8/1.8 = 0.89ROUGE-2 Recall = 2/3 = 0.67ROUGE-2 Precision = 2/4 = 0.5ROUGE-2 F1 = 2 * 0.335/1.17 = 0.57ROUGE-L Recall = 2/4 = 0.5ROUGE-L Precision = 2/5 = 0.4ROUGE-L F1 = 2 * 0.335/1.17 = 0.44
Cut back trouble with the exterior benchmark
The ROUGE Rating is used to grasp how mannequin analysis works. Different benchmarks exist, just like the BLEU Rating. Nevertheless, we can’t virtually construct the dataset to judge our mannequin. We will leverage exterior libraries to benchmark our fashions. Probably the most generally used are the GLUE Benchmark and SuperGLUE Benchmark.
5. Optimize and deploy your mannequin
This step won’t be essential, however lowering computing prices and getting sooner outcomes is at all times good. As soon as your mannequin is prepared, you’ll be able to optimize it to enhance efficiency and scale back reminiscence necessities. We are going to contact on a number of ideas that require extra engineering efforts, data, time, and prices. These ideas will enable you to get acquainted with some methods.
Quantization of the weights
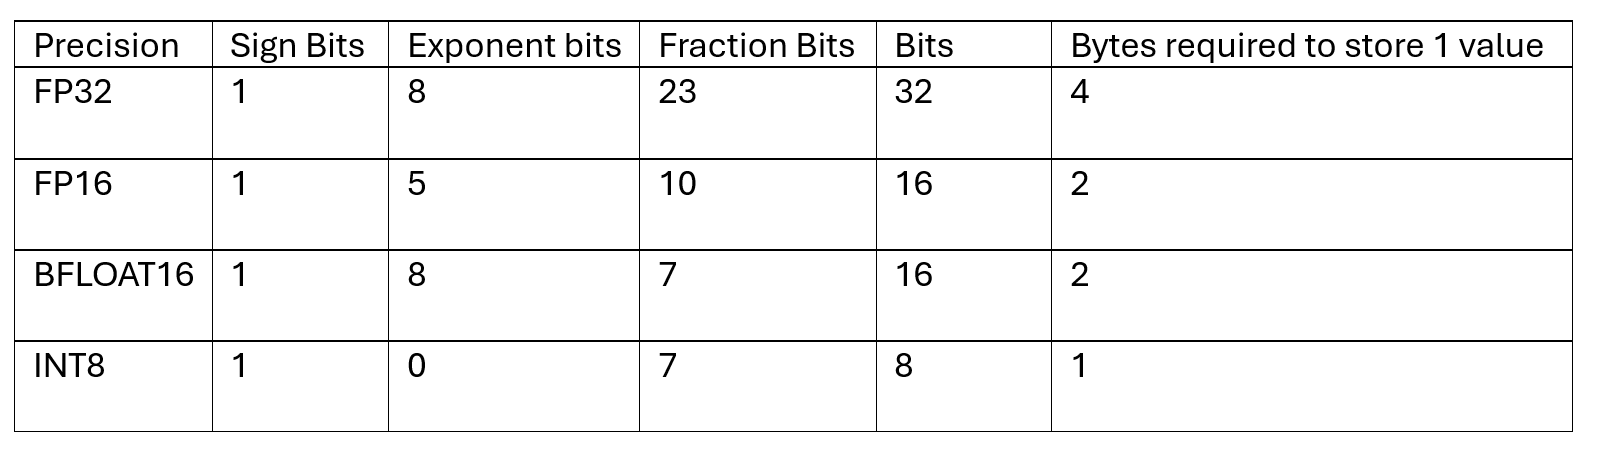
Fashions have parameters, inside variables inside a mannequin which can be realized from information throughout coaching and whose values decide how the mannequin makes predictions. 1 parameter normally requires 24 bytes of processor reminiscence. So, if you happen to select 1B, parameters would require 24 GB of processor reminiscence. Quantization converts the mannequin weights from higher-precision floating-point numbers to lower-precision floating-point numbers for environment friendly storage. Altering the storage precision can considerably have an effect on the variety of bytes required to retailer a single worth of the burden. The desk under illustrates totally different precisions for storing weights.
Pruning
Pruning entails eradicating weights in a mannequin which can be much less vital and have little influence, resembling weights equal to or near zero. Some methods of pruning are a. Full mannequin retrainingb. PEFT like LoRAc. Put up-training.
Conclusion
To conclude, you’ll be able to select a pre-trained mannequin, resembling ChatGPT or FLAN-T5, and construct on high of it. Constructing your pre-trained mannequin requires experience, sources, time, and funds. You possibly can fine-tune it as per your use case if wanted. Then, you need to use your LLM to energy functions and tailor them to your utility use case utilizing methods like RAG. You possibly can consider your mannequin in opposition to some benchmarks to see if it behaves appropriately. You possibly can then deploy your mannequin.
[ad_2]
Source link


