

[ad_1]
We introduce ScreenAI, a vision-language mannequin for consumer interfaces and infographics that achieves state-of-the-art outcomes on UI and infographics-based duties. We’re additionally releasing three new datasets: Display Annotation to guage the format understanding functionality of the mannequin, in addition to ScreenQA Brief and Advanced ScreenQA for a extra complete analysis of its QA functionality.
Display consumer interfaces (UIs) and infographics, equivalent to charts, diagrams and tables, play vital roles in human communication and human-machine interplay as they facilitate wealthy and interactive consumer experiences. UIs and infographics share related design ideas and visible language (e.g., icons and layouts), that provide a chance to construct a single mannequin that may perceive, cause, and work together with these interfaces. Nonetheless, due to their complexity and diversified presentation codecs, infographics and UIs current a singular modeling problem.
To that finish, we introduce “ScreenAI: A Imaginative and prescient-Language Mannequin for UI and Infographics Understanding”. ScreenAI improves upon the PaLI structure with the versatile patching technique from pix2struct. We prepare ScreenAI on a singular combination of datasets and duties, together with a novel Display Annotation job that requires the mannequin to establish UI ingredient info (i.e., kind, location and outline) on a display. These textual content annotations present massive language fashions (LLMs) with display descriptions, enabling them to routinely generate question-answering (QA), UI navigation, and summarization coaching datasets at scale. At solely 5B parameters, ScreenAI achieves state-of-the-art outcomes on UI- and infographic-based duties (WebSRC and MoTIF), and best-in-class efficiency on Chart QA, DocVQA, and InfographicVQA in comparison with fashions of comparable measurement. We’re additionally releasing three new datasets: Display Annotation to guage the format understanding functionality of the mannequin, in addition to ScreenQA Brief and Advanced ScreenQA for a extra complete analysis of its QA functionality.
ScreenAI
ScreenAI’s structure is predicated on PaLI, composed of a multimodal encoder block and an autoregressive decoder. The PaLI encoder makes use of a imaginative and prescient transformer (ViT) that creates picture embeddings and a multimodal encoder that takes the concatenation of the picture and textual content embeddings as enter. This versatile structure permits ScreenAI to resolve imaginative and prescient duties that may be recast as textual content+image-to-text issues.
On prime of the PaLI structure, we make use of a versatile patching technique launched in pix2struct. As an alternative of utilizing a fixed-grid sample, the grid dimensions are chosen such that they protect the native facet ratio of the enter picture. This allows ScreenAI to work properly throughout pictures of assorted facet ratios.
The ScreenAI mannequin is skilled in two phases: a pre-training stage adopted by a fine-tuning stage. First, self-supervised studying is utilized to routinely generate knowledge labels, that are then used to coach ViT and the language mannequin. ViT is frozen through the fine-tuning stage, the place most knowledge used is manually labeled by human raters.
ScreenAI mannequin structure.
Knowledge technology
To create a pre-training dataset for ScreenAI, we first compile an intensive assortment of screenshots from varied units, together with desktops, cell, and tablets. That is achieved through the use of publicly accessible internet pages and following the programmatic exploration method used for the RICO dataset for cell apps. We then apply a format annotator, primarily based on the DETR mannequin, that identifies and labels a variety of UI parts (e.g., picture, pictogram, button, textual content) and their spatial relationships. Pictograms endure additional evaluation utilizing an icon classifier able to distinguishing 77 totally different icon sorts. This detailed classification is crucial for decoding the refined info conveyed via icons. For icons that aren’t lined by the classifier, and for infographics and pictures, we use the PaLI picture captioning mannequin to generate descriptive captions that present contextual info. We additionally apply an optical character recognition (OCR) engine to extract and annotate textual content material on display. We mix the OCR textual content with the earlier annotations to create an in depth description of every display.
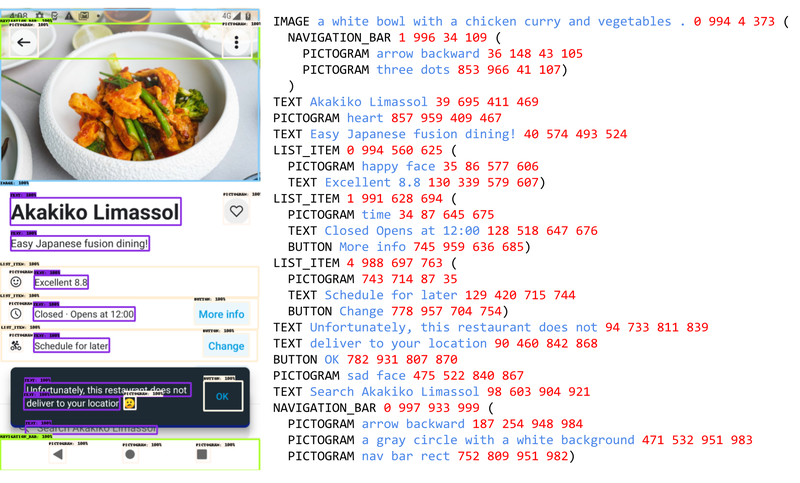
A cell app screenshot with generated annotations that embrace UI parts and their descriptions, e.g., TEXT parts additionally comprise the textual content content material from OCR, IMAGE parts comprise picture captions, LIST_ITEMs comprise all their little one parts.
LLM-based knowledge technology
We improve the pre-training knowledge’s variety utilizing PaLM 2 to generate input-output pairs in a two-step course of. First, display annotations are generated utilizing the method outlined above, then we craft a immediate round this schema for the LLM to create artificial knowledge. This course of requires immediate engineering and iterative refinement to seek out an efficient immediate. We assess the generated knowledge’s high quality via human validation towards a top quality threshold.
The reply must be as quick as potential, containing solely the mandatory info. Your reply must be structured as follows:questions: [{{question: the question,answer: the answer}},…]
{THE SCREEN SCHEMA}
A pattern immediate for QA knowledge technology.
By combining the pure language capabilities of LLMs with a structured schema, we simulate a variety of consumer interactions and situations to generate artificial, real looking duties. Specifically, we generate three classes of duties:
Query answering: The mannequin is requested to reply questions concerning the content material of the screenshots, e.g., “When does the restaurant open?”Display navigation: The mannequin is requested to transform a pure language utterance into an executable motion on a display, e.g., “Click on the search button.”Display summarization: The mannequin is requested to summarize the display content material in a single or two sentences.
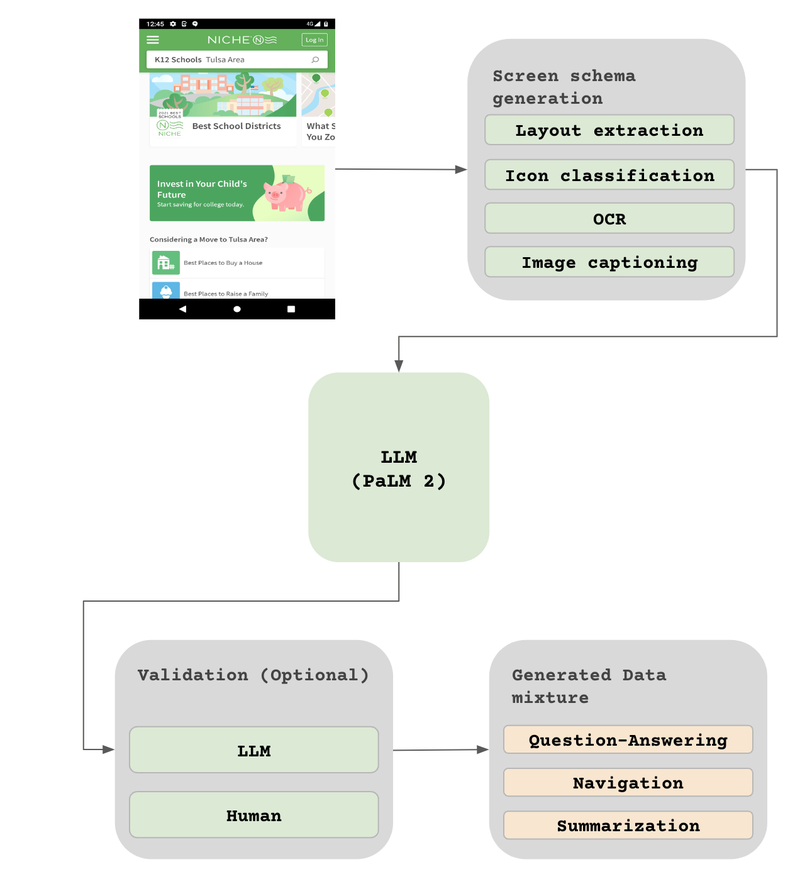
Block diagram of our workflow for producing knowledge for QA, summarization and navigation duties utilizing current ScreenAI fashions and LLMs. Every job makes use of a customized immediate to emphasise desired features, like questions associated to counting, involving reasoning, and many others.
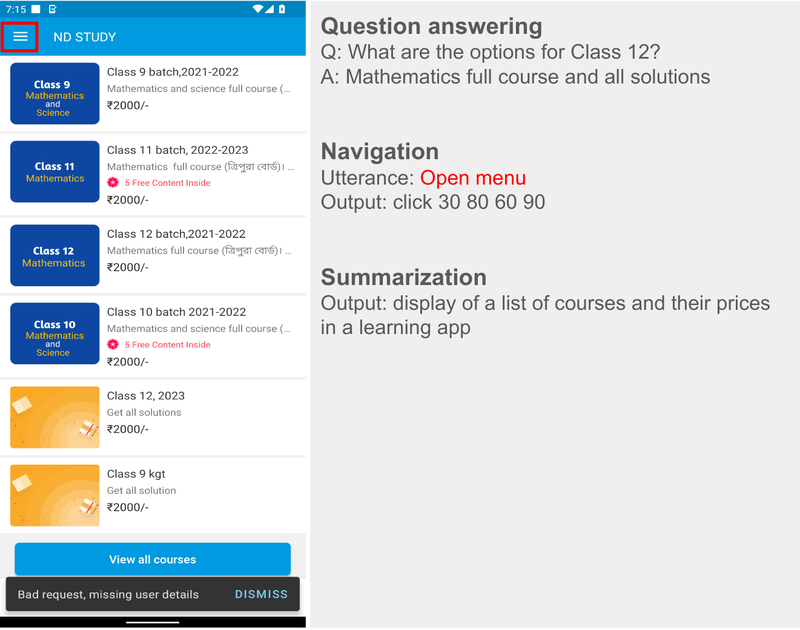
LLM-generated knowledge. Examples for display QA, navigation and summarization. For navigation, the motion bounding field is displayed in crimson on the screenshot.
Experiments and outcomes
As beforehand talked about, ScreenAI is skilled in two phases: pre-training and fine-tuning. Pre-training knowledge labels are obtained utilizing self-supervised studying and fine-tuning knowledge labels comes from human raters.
We fine-tune ScreenAI utilizing public QA, summarization, and navigation datasets and quite a lot of duties associated to UIs. For QA, we use properly established benchmarks within the multimodal and doc understanding area, equivalent to ChartQA, DocVQA, Multi web page DocVQA, InfographicVQA, OCR VQA, Internet SRC and ScreenQA. For navigation, datasets used embrace Referring Expressions, MoTIF, Mug, and Android within the Wild. Lastly, we use Screen2Words for display summarization. Together with the fine-tuning datasets, we consider the fine-tuned ScreenAI mannequin utilizing three novel benchmarks:
Display Annotation: Allows the analysis mannequin format annotations and spatial understanding capabilities.ScreenQA Brief: A variation of ScreenQA, the place its floor fact solutions have been shortened to comprise solely the related info that higher aligns with different QA duties.Advanced ScreenQA: Enhances ScreenQA Brief with tougher questions (counting, arithmetic, comparability, and non-answerable questions) and comprises screens with varied facet ratios.
The fine-tuned ScreenAI mannequin achieves state-of-the-art outcomes on varied UI and infographic-based duties (WebSRC and MoTIF) and best-in-class efficiency on Chart QA, DocVQA, and InfographicVQA in comparison with fashions of comparable measurement. ScreenAI achieves aggressive efficiency on Screen2Words and OCR-VQA. Moreover, we report outcomes on the brand new benchmark datasets launched to function a baseline for additional analysis.
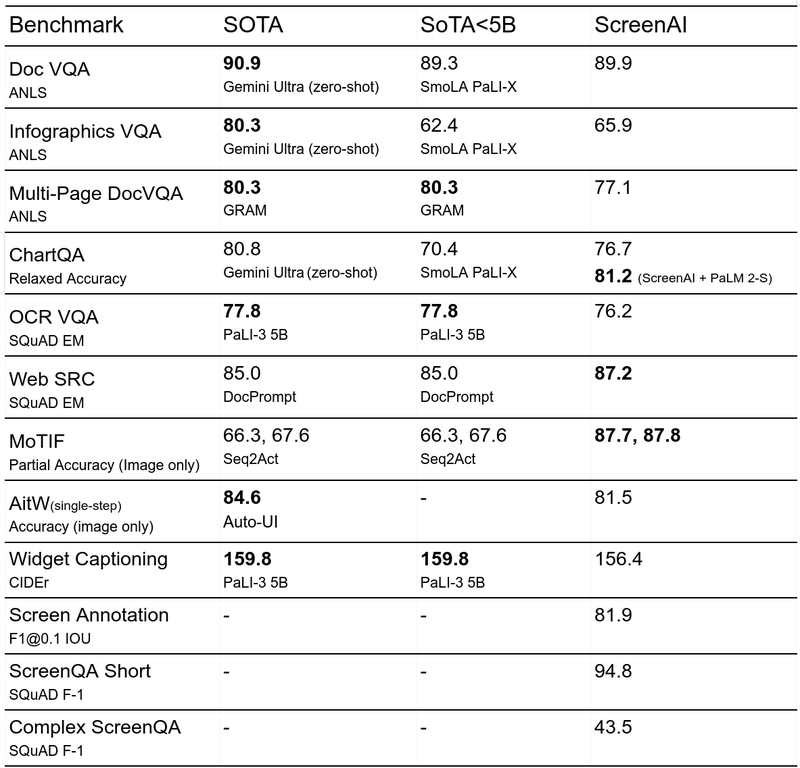
Evaluating mannequin efficiency of ScreenAI with state-of-the-art (SOTA) fashions of comparable measurement.
Subsequent, we study ScreenAI’s scaling capabilities and observe that throughout all duties, rising the mannequin measurement improves performances and the enhancements haven’t saturated on the largest measurement.
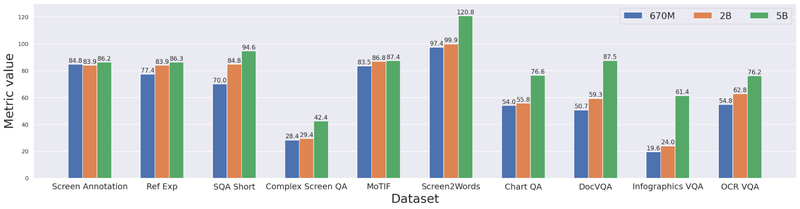
Mannequin efficiency will increase with measurement, and the efficiency has not saturated even on the largest measurement of 5B params.
Conclusion
We introduce the ScreenAI mannequin together with a unified illustration that allows us to develop self-supervised studying duties leveraging knowledge from all these domains. We additionally illustrate the influence of information technology utilizing LLMs and examine bettering mannequin efficiency on particular features with modifying the coaching combination. We apply all of those methods to construct multi-task skilled fashions that carry out competitively with state-of-the-art approaches on various public benchmarks. Nonetheless, we additionally notice that our method nonetheless lags behind massive fashions and additional analysis is required to bridge this hole.
Acknowledgements
This challenge is the results of joint work with Maria Wang, Fedir Zubach, Hassan Mansoor, Vincent Etter, Victor Carbune, Jason Lin, Jindong Chen and Abhanshu Sharma. We thank Fangyu Liu, Xi Chen, Efi Kokiopoulou, Jesse Berent, Gabriel Barcik, Lukas Zilka, Oriana Riva, Gang Li,Yang Li, Radu Soricut, and Tania Bedrax-Weiss for his or her insightful suggestions and discussions, together with Rahul Aralikatte, Hao Cheng and Daniel Kim for his or her help in knowledge preparation. We additionally thank Jay Yagnik, Blaise Aguera y Arcas, Ewa Dominowska, David Petrou, and Matt Sharifi for his or her management, imaginative and prescient and help. We’re very grateful toTom Small for serving to us create the animation on this submit.
[ad_2]
Source link


