

[ad_1]
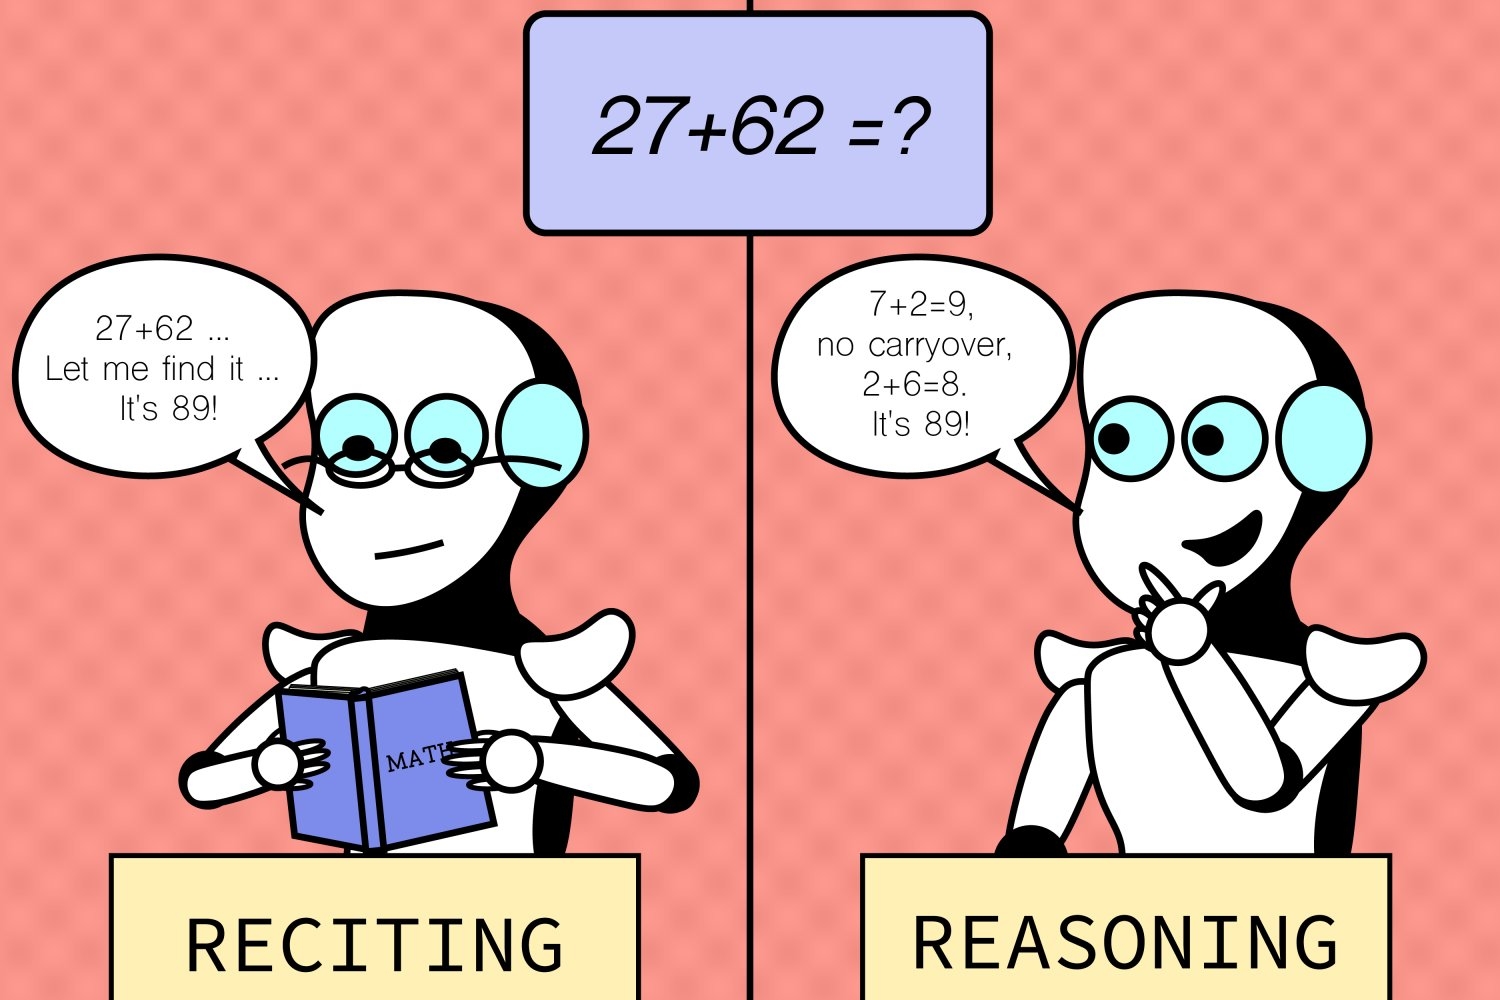
On the subject of synthetic intelligence, appearances will be deceiving. The thriller surrounding the interior workings of huge language fashions (LLMs) stems from their huge dimension, advanced coaching strategies, hard-to-predict behaviors, and elusive interpretability.
MIT’s Laptop Science and Synthetic Intelligence Laboratory (CSAIL) researchers just lately peered into the proverbial magnifying glass to look at how LLMs fare with variations of various duties, revealing intriguing insights into the interaction between memorization and reasoning expertise. It seems that their reasoning talents are sometimes overestimated.
The examine in contrast “default duties,” the frequent duties a mannequin is skilled and examined on, with “counterfactual eventualities,” hypothetical conditions deviating from default situations — which fashions like GPT-4 and Claude can often be anticipated to deal with. The researchers developed some assessments exterior the fashions’ consolation zones by tweaking present duties as an alternative of making totally new ones. They used a wide range of datasets and benchmarks particularly tailor-made to totally different points of the fashions’ capabilities for issues like arithmetic, chess, evaluating code, answering logical questions, and so forth.
When customers work together with language fashions, any arithmetic is often in base-10, the acquainted quantity base to the fashions. However observing that they do properly on base-10 might give us a misunderstanding of them having robust competency as well as. Logically, if they honestly possess good addition expertise, you’d count on reliably excessive efficiency throughout all quantity bases, much like calculators or computer systems. Certainly, the analysis confirmed that these fashions are usually not as strong as many initially suppose. Their excessive efficiency is proscribed to frequent activity variants and endure from constant and extreme efficiency drop within the unfamiliar counterfactual eventualities, indicating an absence of generalizable addition means.
The sample held true for a lot of different duties like musical chord fingering, spatial reasoning, and even chess issues the place the beginning positions of items have been barely altered. Whereas human gamers are anticipated to nonetheless be capable of decide the legality of strikes in altered eventualities (given sufficient time), the fashions struggled and couldn’t carry out higher than random guessing, that means they’ve restricted means to generalize to unfamiliar conditions. And far of their efficiency on the usual duties is probably going not resulting from basic activity talents, however overfitting to, or immediately memorizing from, what they’ve seen of their coaching information.
“We’ve uncovered a captivating facet of huge language fashions: they excel in acquainted eventualities, nearly like a well-worn path, however wrestle when the terrain will get unfamiliar. This perception is essential as we attempt to boost these fashions’ adaptability and broaden their software horizons,” says Zhaofeng Wu, an MIT PhD pupil in electrical engineering and pc science, CSAIL affiliate, and the lead creator on a brand new paper in regards to the analysis. “As AI is turning into more and more ubiquitous in our society, it should reliably deal with numerous eventualities, whether or not acquainted or not. We hope these insights will at some point inform the design of future LLMs with improved robustness.”
Regardless of the insights gained, there are, in fact, limitations. The examine’s give attention to particular duties and settings didn’t seize the total vary of challenges the fashions might probably encounter in real-world purposes, signaling the necessity for extra numerous testing environments. Future work might contain increasing the vary of duties and counterfactual situations to uncover extra potential weaknesses. This might imply extra advanced and fewer frequent eventualities. The crew additionally needs to enhance interpretability by creating strategies to higher comprehend the rationale behind the fashions’ decision-making processes.
“As language fashions scale up, understanding their coaching information turns into more and more difficult even for open fashions, not to mention proprietary ones,” says Hao Peng, assistant professor on the College of Illinois at Urbana-Champaign. “The group stays puzzled about whether or not these fashions genuinely generalize to unseen duties, or seemingly succeed by memorizing the coaching information. This paper makes necessary strides in addressing this query. It constructs a set of rigorously designed counterfactual evaluations, offering recent insights into the capabilities of state-of-the-art LLMs. It reveals that their means to unravel unseen duties is probably much more restricted than anticipated by many. It has the potential to encourage future analysis in direction of figuring out the failure modes of at the moment’s fashions and creating higher ones.”
Further authors embody Najoung Kim, who’s a Boston College assistant professor and Google visiting researcher, and 7 CSAIL associates: MIT electrical engineering and pc science (EECS) PhD college students Linlu Qiu, Alexis Ross, Ekin Akyürek SM ’21, and Boyuan Chen; former postdoc and Apple AI/ML researcher Bailin Wang; and EECS assistant professors Jacob Andreas and Yoon Kim.
The crew’s examine was supported, partly, by the MIT–IBM Watson AI Lab, the MIT Quest for Intelligence, and the Nationwide Science Basis. The crew offered the work on the North American Chapter of the Affiliation for Computational Linguistics (NAACL) final month.
[ad_2]
Source link

