

[ad_1]
We current Cappy, a small pre-trained scorer mannequin that enhances and surpasses the efficiency of enormous multi-task language fashions. We consider the effectiveness of this pre-training scorer throughout quite a lot of complicated duties from PromptSource and Huge-Bench.
Giant language mannequin (LLM) developments have led to a brand new paradigm that unifies varied pure language processing (NLP) duties inside an instruction-following framework. This paradigm is exemplified by current multi-task LLMs, reminiscent of T0, FLAN, and OPT-IML. First, multi-task knowledge is gathered with every job following a task-specific template, the place every labeled instance is transformed into an instruction (e.g., “Put the ideas collectively to kind a sentence: ski, mountain, skier”) paired with a corresponding response (e.g., “Skier skis down the mountain”). These instruction-response pairs are used to coach the LLM, leading to a conditional technology mannequin that takes an instruction as enter and generates a response. Furthermore, multi-task LLMs have exhibited exceptional task-wise generalization capabilities as they will deal with unseen duties by understanding and fixing brand-new directions.
The demonstration of the instruction-following pre-training of multi-task LLMs, e.g., FLAN. Pre-training duties below this paradigm improves the efficiency for unseen duties.
As a result of complexity of understanding and fixing varied duties solely utilizing directions, the scale of multi-task LLMs usually spans from a number of billion parameters to tons of of billions (e.g., FLAN-11B, T0-11B and OPT-IML-175B). In consequence, working such sizable fashions poses important challenges as a result of they demand appreciable computational energy and impose substantial necessities on the reminiscence capacities of GPUs and TPUs, making their coaching and inference costly and inefficient. In depth storage is required to take care of a novel LLM copy for every downstream job. Furthermore, essentially the most highly effective multi-task LLMs (e.g., FLAN-PaLM-540B) are closed-sourced, making them unimaginable to be tailored. Nevertheless, in sensible functions, harnessing a single multi-task LLM to handle all conceivable duties in a zero-shot method stays troublesome, significantly when coping with complicated duties, personalised duties and people that can not be succinctly outlined utilizing directions. However, the scale of downstream coaching knowledge is normally inadequate to coach a mannequin properly with out incorporating wealthy prior information. Therefore, it’s lengthy desired to adapt LLMs with downstream supervision whereas bypassing storage, reminiscence, and entry points.
Sure parameter-efficient tuning methods, together with immediate tuning and adapters, considerably diminish storage necessities, however they nonetheless carry out back-propagation by LLM parameters in the course of the tuning course of, thereby maintaining their reminiscence calls for excessive. Moreover, some in-context studying strategies circumvent parameter tuning by integrating a restricted variety of supervised examples into the instruction. Nevertheless, these strategies are constrained by the mannequin’s most enter size, which allows just a few samples to information job decision.
In “Cappy: Outperforming and Boosting Giant Multi-Process LMs with a Small Scorer”, offered at NeurIPS 2023, we suggest a novel strategy that enhances the efficiency and effectivity of multi-task LLMs. We introduce a light-weight pre-trained scorer, Cappy, based mostly on continuous pre-training on high of RoBERTa with merely 360 million parameters. Cappy takes in an instruction and a candidate response as enter, and produces a rating between 0 and 1, indicating an estimated correctness of the response with respect to the instruction. Cappy capabilities both independently on classification duties or serves as an auxiliary part for LLMs, boosting their efficiency. Furthermore, Cappy effectively permits downstream supervision with out requiring any finetuning, which avoids the necessity for back-propagation by LLM parameters and reduces reminiscence necessities. Lastly, adaptation with Cappy doesn’t require entry to LLM parameters as it’s appropriate with closed-source multi-task LLMs, reminiscent of these solely accessible by way of WebAPIs.
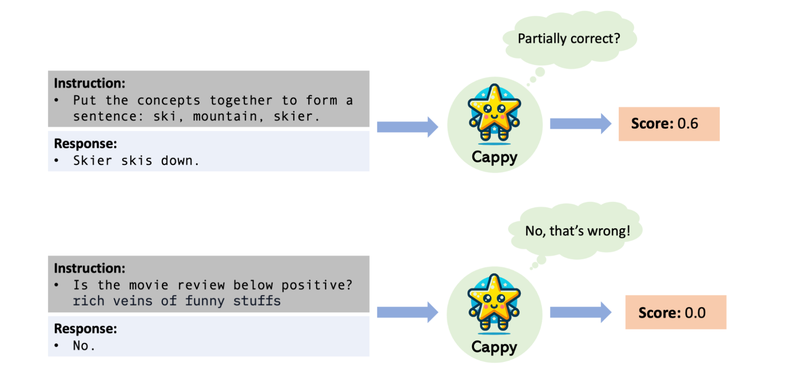
Cappy takes an instruction and response pair as enter and outputs a rating starting from 0 to 1, indicating an estimation of the correctness of the response with respect to the instruction.
Pre-training
We start with the identical dataset assortment, which incorporates 39 numerous datasets from PromptSource that have been used to coach T0. This assortment encompasses a variety of job sorts, reminiscent of query answering, sentiment evaluation, and summarization. Every dataset is related to a number of templates that convert every occasion from the unique datasets into an instruction paired with its floor reality response.
Cappy’s regression modeling requires every pre-training knowledge occasion to incorporate an instruction-response pair together with a correctness annotation for the response, so we produce a dataset with correctness annotations that vary from 0 to 1. For each occasion inside a technology job, we leverage an present multi-task LLM to generate a number of responses by sampling, conditioned on the given instruction. Subsequently, we assign an annotation to the pair shaped by the instruction and each response, utilizing the similarity between the response and the bottom reality response of the occasion. Particularly, we make use of Rouge-L, a commonly-used metric for measuring total multi-task efficiency that has demonstrated a robust alignment with human analysis, to calculate this similarity as a type of weak supervision.
In consequence, we receive an efficient regression dataset of 160 million situations paired with correctness rating annotations. The ultimate Cappy mannequin is the results of steady pre-training utilizing the regression dataset on high of the RoBERTa mannequin. The pre-training of Cappy is carried out on Google’s TPU-v4, with RedCoast, a light-weight toolkit for automating distributed coaching.
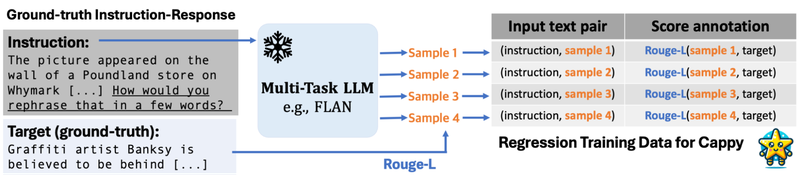
Information augmentation with a multi-task LLM to assemble a weakly supervised regression dataset for Cappy’s pre-training and fine-tuning.
Making use of Cappy
Cappy solves sensible duties inside a candidate-selection mechanism. Extra particularly, given an instruction and a set of candidate responses, Cappy produces a rating for every candidate response. That is achieved by inputting the instruction alongside every particular person response, after which assigning the response with the very best rating as its prediction. In classification duties, all candidate responses are inherently predefined. For instance, for an instruction of a sentiment classification job (e.g., “Based mostly on this assessment, would the person suggest this product?: ‘Beautiful even for the non-gamer.’”), the candidate responses are “Sure” or “No”. In such eventualities, Cappy capabilities independently. However, in technology duties, candidate responses are usually not pre-defined, requiring an present multi-task LLM to yield the candidate responses. On this case, Cappy serves as an auxiliary part of the multi-task LLM, enhancing its decoding.
Adapting multi-task LLMs with Cappy
When there may be obtainable downstream coaching knowledge, Cappy permits efficient and environment friendly adaptation of multi-task LLMs on downstream duties. Particularly, we fine-tune Cappy to combine downstream job info into LLM predictions. This course of includes making a separate regression dataset particular to the downstream coaching knowledge with the identical knowledge annotation course of used to assemble the pre-training knowledge. In consequence, the fine-tuned Cappy collaborates with a multi-task LLM, boosting the LLM’s efficiency on the downstream job.
In distinction to different LLM tuning methods, adapting LLMs with Cappy considerably reduces the excessive demand for gadget reminiscence because it avoids the necessity for back-propagation by LLM parameters for downstream duties. Furthermore, Cappy adaptation doesn’t depend on the entry to LLM parameters, making it appropriate with closed-source multi-task LLMs, reminiscent of those solely accessible by way of WebAPIs. In contrast with in-context studying approaches, which circumvent mannequin tuning by attaching coaching examples to the instruction prefix, Cappy will not be restricted by the LLM’s most enter size. Thus, Cappy can incorporate a vast variety of downstream coaching examples. Cappy can be utilized with different adaptation strategies, reminiscent of fine-tuning and in-context studying, additional boosting their total efficiency.
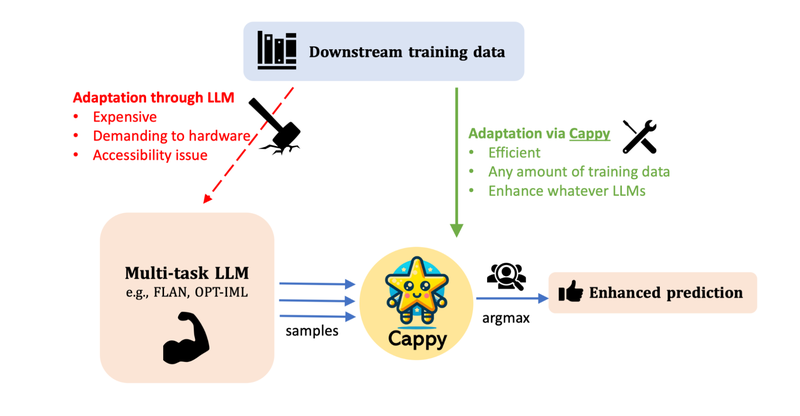
Downstream adaptation comparability between Cappy and approaches that depend on an LLM’s parameters, reminiscent of fine-tuning and immediate tuning. Cappy’s software enhances multi-task LLMs.
Outcomes
We assess Cappy’s efficiency throughout eleven held-out language understanding classification duties from PromptSource. We display that Cappy, with 360M parameters, outperforms OPT-175B and OPT-IML-30B, and matches the accuracy of one of the best present multi-task LLMs (T0-11B and OPT-IML-175B). These findings spotlight Cappy’s capabilities and parameter effectivity, which could be credited to its scoring-based pre-training technique that integrates contrastive info by differentiating between high-quality and low-quality responses. Quite the opposite, earlier multi-task LLMs rely solely on teacher-forcing coaching that makes use of solely the bottom reality responses.
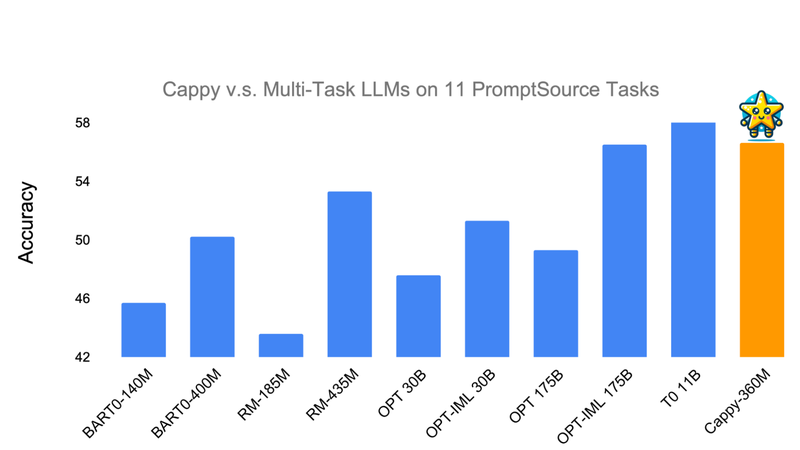
The general accuracy averaged over eleven check duties from PromptSource. “RM” refers to a pre-trained RLHF reward mannequin. Cappy matches one of the best ones amongst present multi-task LLMs.
We additionally look at the difference of multi-task LLMs with Cappy on complicated duties from BIG-Bench, a set of manually curated duties which are thought of past the aptitude of many LLMs. We deal with all of the 45 technology BIG-Bench duties, particularly these that don’t supply pre-established reply decisions. We consider the efficiency utilizing the Rouge-L rating (representing the general similarity between mannequin generations and corresponding floor truths) on each check set, reporting the common rating throughout 45 assessments. On this experiment, all variants of FLAN-T5 function the spine LLMs, and the foundational FLAN-T5 fashions are frozen. These outcomes, proven under, recommend that Cappy enhances the efficiency of FLAN-T5 fashions by a big margin, constantly outperforming the simplest baseline achieved by pattern choice utilizing self-scoring of the LLM itself.
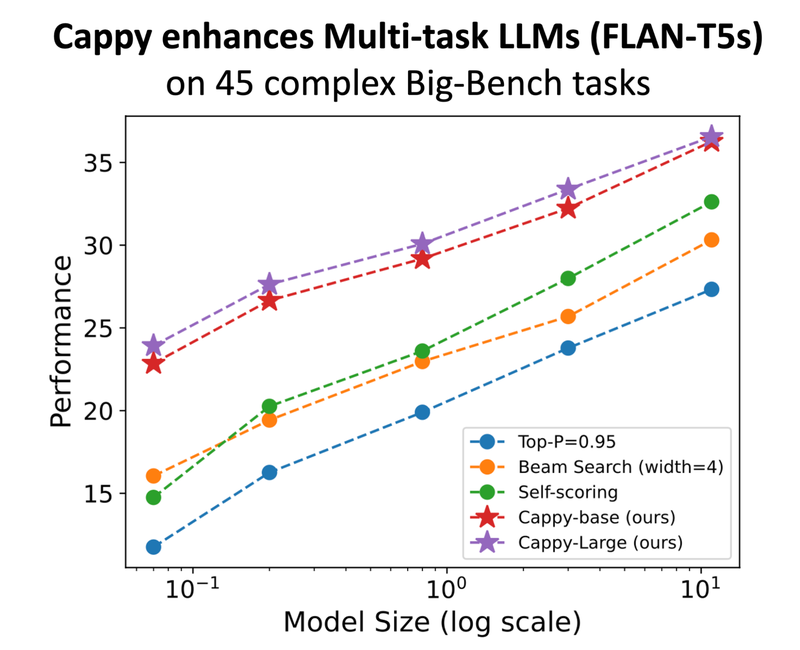
The averaged Rouge-L rating over 45 complicated duties inside BIG-Bench. The x-axis refers to FLAN-T5 fashions of various sizes. Each dashed line represents an strategy engaged on FLAN-T5s. Self-scoring refers to utilizing the cross-entropy of LLM to pick responses. Cappy enhances the efficiency of FLAN-T5 fashions by a big margin.
Conclusion
We introduce Cappy, a novel strategy that enhances the efficiency and effectivity of multi-task LLMs. In our experiments, we adapt a single LLM to a number of domains with Cappy. Sooner or later, Cappy as a pre-trained mannequin can probably be utilized in different artistic methods past on single LLMs.
Acknowledgments
Because of Bowen Tan, Jindong Chen, Lei Meng, Abhanshu Sharma and Ewa Dominowska for his or her precious suggestions. We’d additionally prefer to thank Eric Xing and Zhiting Hu for his or her solutions.
[ad_2]
Source link


