

[ad_1]
Editor’s Word: This text follows Pure Language processing methods that enhance knowledge high quality with LLMs and Toxicity, bias, and unhealthy actors: three issues to consider when utilizing LLMs.
We regularly hear about cyberattacks, hackers, ransomware, and different nefarious deeds within the information, however not all knowledge breaches are attributable to third events. In 2023, the Identification Theft Useful resource Middle reported a complete of three,205 breaches with over 350M victims. System and human errors accounted for over 700 of those breaches with almost 7M victims.
Exploring LLM-related knowledge breaches
Most organizations allocate appreciable time, cash, and assets to forestall knowledge breaches; from coaching staff on the way to correctly retailer and defend firm knowledge to fixed community monitoring. Giant language fashions (LLMs) add a brand new variable to the equation.
In a earlier article, I touched on pure language processing (NLP) methods that can be utilized to enhance knowledge high quality in unstructured knowledge. I discussed that exposing LLMs to domain-related textual content knowledge isn’t all the time the best choice due to attainable duplication, ambiguity, and noise. Moreover, you will need to make it possible for knowledge inputted into LLMs doesn’t include personally identifiable or in any other case delicate data. If delicate knowledge makes its approach into the mannequin, unhealthy actors might use immediate assaults to affect the mannequin to disclose delicate knowledge it has seen or has entry to. As soon as LLMs have seen delicate knowledge, it’s troublesome to get them to take away or delete it with out going again to a baseline and going by the fine-tuning course of once more. The identical modeling methods used to handle noise will also be used to detect personal or delicate knowledge in coaching knowledge so it may be redacted or the data containing it excluded from fine-tuning.
Figuring out organizational dangers
Preserving personal and delicate data out of LLMs when getting ready them for area use in a company is one piece of the puzzle, however there’s one other facet that many fail to contemplate—customers who make unhealthy selections and inadvertently put their organizations in danger.
A senior govt at a big group was telling me about a few of the methods his division was experimenting with free variations of publicly obtainable LLMs and the superb insights they had been gleaning. He defined that they had been making an attempt to raised perceive buyer satisfaction utilizing their name middle buyer narratives and had been copying and pasting narrative data into their prompts. That raised a pink flag for me.
I requested if the narratives contained any personally identifiable data, and he confirmed that a few of them contained names, handle data, and infrequently account data. I then requested him if he’d learn the phrases of service for the fashions they had been experimenting with. He requested why, and I discussed that some fashions use immediate data for additional coaching. He went silent for a minute, then requested how he might get that data again out of the mannequin if it had been uncovered, and I defined that he possible couldn’t. Even when the LLM had been hosted internally, copying and pasting data containing probably delicate data and utilizing it in prompts would possible nonetheless be a violation of safety protocols.
Understanding LLM phrases of service
There are such a lot of fashions obtainable, and other people introduce knowledge into them on a regular basis—whether or not it’s a content material marketer making an attempt to get assist writing advertising and marketing copy that has a sure voice, a pupil copying and pasting studying passages asking for assist with a homework task, or somebody making an attempt to glean insights from buyer narratives. I converse to many individuals about LLMs, each as a product supervisor and in my instructing position at Duke College, and the lack of know-how that, relying on the mannequin, prompts will be retained and used for additional coaching is pervasive. It’s essential to know how the fashions you select use data out of your prompts.
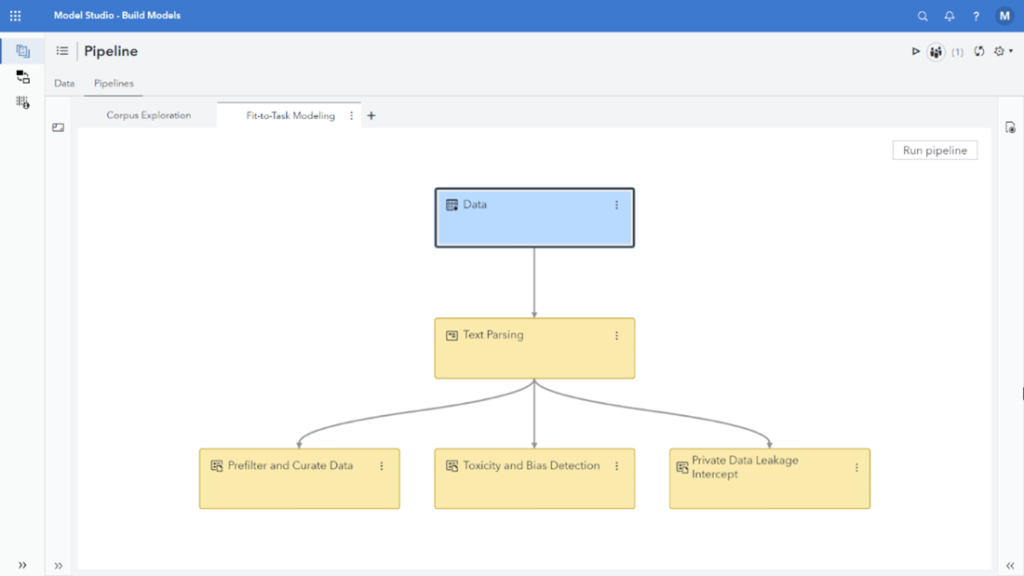
As a result of folks could unknowingly violate safety protocols when prompting LLMs, it’s attainable to take the identical sort of linguistic mannequin that will be used to determine and redact delicate data earlier than fine-tuning and deploy it between a immediate and an LLM. The linguistic mannequin might then intercept prompts that include PII or delicate knowledge and forestall it from being launched into the LLM. This supplies an added layer of safety, and since linguistic fashions run so effectively, the scanning and intercept will be accomplished with no vital affect on efficiency.
Lowering threat requires accountability
Because the adoption of LLMs continues to develop, so does the chance of unintentionally exposing delicate knowledge by careless prompting. The examples I’ve shared underscore the necessity for organizations to be vigilant about how they work together with these highly effective instruments, however consciousness is simply step one.
Stopping personal and delicate knowledge leakage isn’t simply the duty of the IT division. It’s a shared duty throughout total organizations. Educating groups on potential dangers, rigorously vetting the LLMs you select, and integrating linguistic fashions as one other layer to intercept or redact delicate data earlier than it reaches the LLM might help scale back dangers. By staying knowledgeable and proactive, you’ll be able to leverage the advantages of LLMs whereas safeguarding a few of your group’s Most worthy belongings—your knowledge and your fame.
Be taught extra
[ad_2]
Source link


