

[ad_1]
Introduction
Many generative AI use circumstances nonetheless revolve round Retrieval Augmented Technology (RAG), but persistently fall wanting consumer expectations. Regardless of the rising physique of analysis on RAG enhancements and even including Brokers into the method, many options nonetheless fail to return exhaustive outcomes, miss info that’s important however sometimes talked about within the paperwork, require a number of search iterations, and customarily battle to reconcile key themes throughout a number of paperwork. To prime all of it off, many implementations nonetheless depend on cramming as a lot “related” info as potential into the mannequin’s context window alongside detailed system and consumer prompts. Reconciling all this info usually exceeds the mannequin’s cognitive capability and compromises response high quality and consistency.
That is the place our Agentic Data Distillation + Pyramid Search Method comes into play. As an alternative of chasing the very best chunking technique, retrieval algorithm, or inference-time reasoning technique, my group, Jim Brown, Mason Sawtell, Sandi Besen, and I, take an agentic strategy to doc ingestion.
We leverage the total functionality of the mannequin at ingestion time to focus solely on distilling and preserving probably the most significant info from the doc dataset. This essentially simplifies the RAG course of by permitting the mannequin to direct its reasoning talents towards addressing the consumer/system directions relatively than struggling to know formatting and disparate info throughout doc chunks.
We particularly goal high-value questions which are usually troublesome to judge as a result of they’ve a number of right solutions or resolution paths. These circumstances are the place conventional RAG options battle most and present RAG analysis datasets are largely inadequate for testing this downside house. For our analysis implementation, we downloaded annual and quarterly reviews from the final 12 months for the 30 firms within the DOW Jones Industrial Common. These paperwork may be discovered by the SEC EDGAR web site. The data on EDGAR is accessible and in a position to be downloaded without spending a dime or may be queried by EDGAR public searches. See the SEC privateness coverage for added particulars, info on the SEC web site is “thought of public info and could also be copied or additional distributed by customers of the website online with out the SEC’s permission”. We chosen this dataset for 2 key causes: first, it falls outdoors the data cutoff for the fashions evaluated, guaranteeing that the fashions can not reply to questions based mostly on their data from pre-training; second, it’s an in depth approximation for real-world enterprise issues whereas permitting us to debate and share our findings utilizing publicly accessible information.
Whereas typical RAG options excel at factual retrieval the place the reply is well recognized within the doc dataset (e.g., “When did Apple’s annual shareholder’s assembly happen?”), they battle with nuanced questions that require a deeper understanding of ideas throughout paperwork (e.g., “Which of the DOW firms has probably the most promising AI technique?”). Our Agentic Data Distillation + Pyramid Search Method addresses all these questions with a lot higher success in comparison with different normal approaches we examined and overcomes limitations related to utilizing data graphs in RAG techniques.
On this article, we’ll cowl how our data distillation course of works, key advantages of this strategy, examples, and an open dialogue on one of the simplest ways to judge all these techniques the place, in lots of circumstances, there isn’t any singular “proper” reply.
Constructing the pyramid: How Agentic Data Distillation works
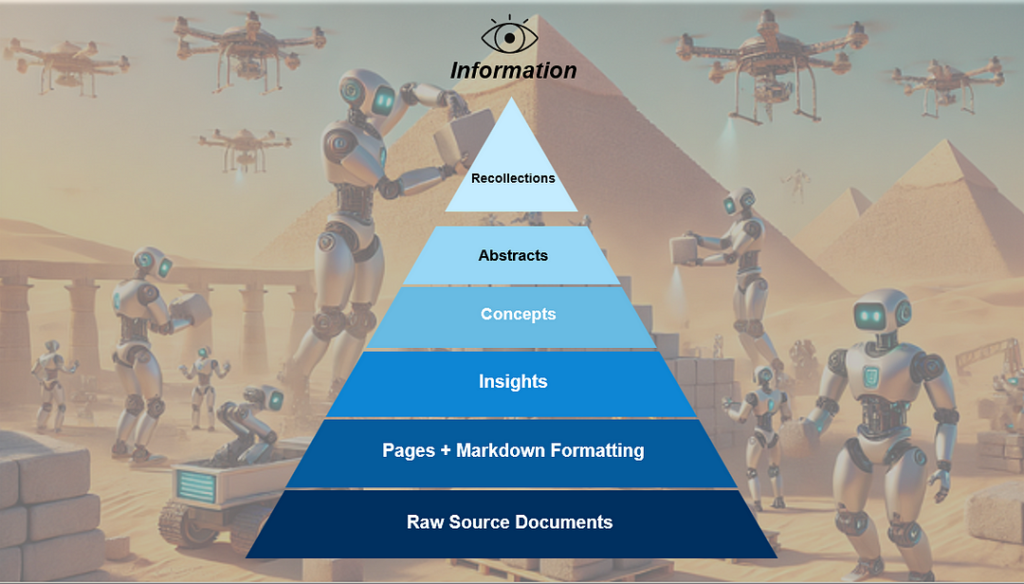
Overview
Our data distillation course of creates a multi-tiered pyramid of data from the uncooked supply paperwork. Our strategy is impressed by the pyramids utilized in deep studying laptop vision-based duties, which permit a mannequin to research a picture at a number of scales. We take the contents of the uncooked doc, convert it to markdown, and distill the content material into an inventory of atomic insights, associated ideas, doc abstracts, and basic recollections/recollections. Throughout retrieval it’s potential to entry all or any ranges of the pyramid to answer the consumer request.
Easy methods to distill paperwork and construct the pyramid:
Convert paperwork to Markdown: Convert all uncooked supply paperwork to Markdown. We’ve discovered fashions course of markdown finest for this process in comparison with different codecs like JSON and it’s extra token environment friendly. We used Azure Doc Intelligence to generate the markdown for every web page of the doc, however there are various different open-source libraries like MarkItDown which do the identical factor. Our dataset included 331 paperwork and 16,601 pages.
Extract atomic insights from every web page: We course of paperwork utilizing a two-page sliding window, which permits every web page to be analyzed twice. This offers the agent the chance to right any potential errors when processing the web page initially. We instruct the mannequin to create a numbered record of insights that grows because it processes the pages within the doc. The agent can overwrite insights from the earlier web page in the event that they have been incorrect because it sees every web page twice. We instruct the mannequin to extract insights in easy sentences following the subject-verb-object (SVO) format and to jot down sentences as if English is the second language of the consumer. This considerably improves efficiency by encouraging readability and precision. Rolling over every web page a number of occasions and utilizing the SVO format additionally solves the disambiguation downside, which is a big problem for data graphs. The perception technology step can also be significantly useful for extracting info from tables for the reason that mannequin captures the details from the desk in clear, succinct sentences. Our dataset produced 216,931 complete insights, about 13 insights per web page and 655 insights per doc.
Distilling ideas from insights: From the detailed record of insights, we establish higher-level ideas that join associated details about the doc. This step considerably reduces noise and redundant info within the doc whereas preserving important info and themes. Our dataset produced 14,824 complete ideas, about 1 idea per web page and 45 ideas per doc.
Creating abstracts from ideas: Given the insights and ideas within the doc, the LLM writes an summary that seems each higher than any summary a human would write and extra information-dense than any summary current within the authentic doc. The LLM generated summary supplies extremely complete data concerning the doc with a small token density that carries a major quantity of data. We produce one summary per doc, 331 complete.
Storing recollections/recollections throughout paperwork: On the prime of the pyramid we retailer important info that’s helpful throughout all duties. This may be info that the consumer shares concerning the process or info the agent learns concerning the dataset over time by researching and responding to duties. For instance, we will retailer the present 30 firms within the DOW as a recollection since this record is completely different from the 30 firms within the DOW on the time of the mannequin’s data cutoff. As we conduct increasingly more analysis duties, we will constantly enhance our recollections and keep an audit path of which paperwork these recollections originated from. For instance, we will preserve monitor of AI methods throughout firms, the place firms are making main investments, and many others. These high-level connections are tremendous necessary since they reveal relationships and data that aren’t obvious in a single web page or doc.
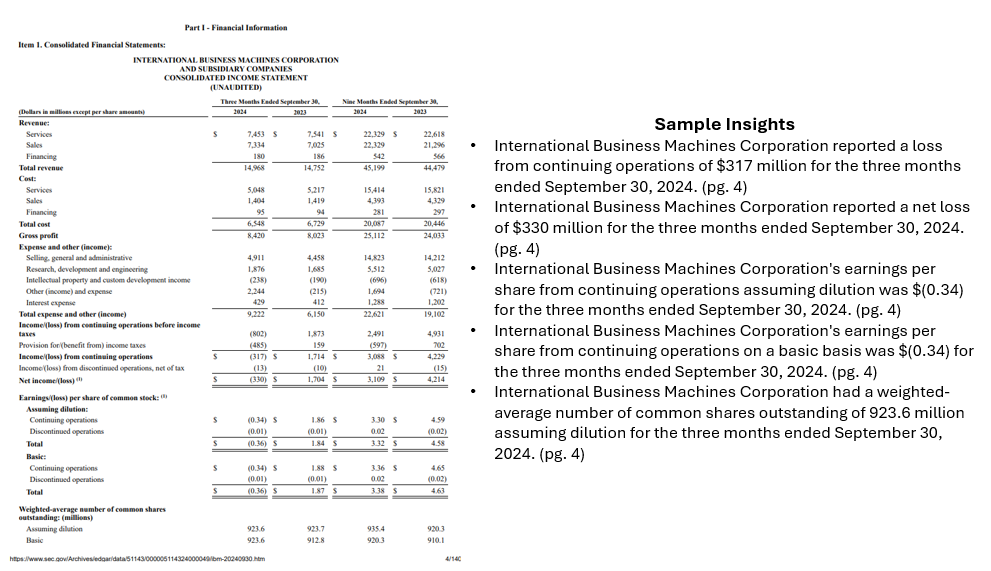
We retailer the textual content and embeddings for every layer of the pyramid (pages and up) in Azure PostgreSQL. We initially used Azure AI Search, however switched to PostgreSQL for value causes. This required us to jot down our personal hybrid search perform since PostgreSQL doesn’t but natively help this characteristic. This implementation would work with any vector database or vector index of your selecting. The important thing requirement is to retailer and effectively retrieve each textual content and vector embeddings at any degree of the pyramid.
This strategy primarily creates the essence of a data graph, however shops info in pure language, the best way an LLM natively desires to work together with it, and is extra environment friendly on token retrieval. We additionally let the LLM choose the phrases used to categorize every degree of the pyramid, this appeared to let the mannequin resolve for itself one of the simplest ways to explain and differentiate between the data saved at every degree. For instance, the LLM most popular “insights” to “details” because the label for the primary degree of distilled data. Our purpose in doing this was to raised perceive how an LLM thinks concerning the course of by letting it resolve easy methods to retailer and group associated info.
Utilizing the pyramid: The way it works with RAG & Brokers
At inference time, each conventional RAG and agentic approaches profit from the pre-processed, distilled info ingested in our data pyramid. The pyramid construction permits for environment friendly retrieval in each the standard RAG case, the place solely the highest X associated items of data are retrieved or within the Agentic case, the place the Agent iteratively plans, retrieves, and evaluates info earlier than returning a closing response.
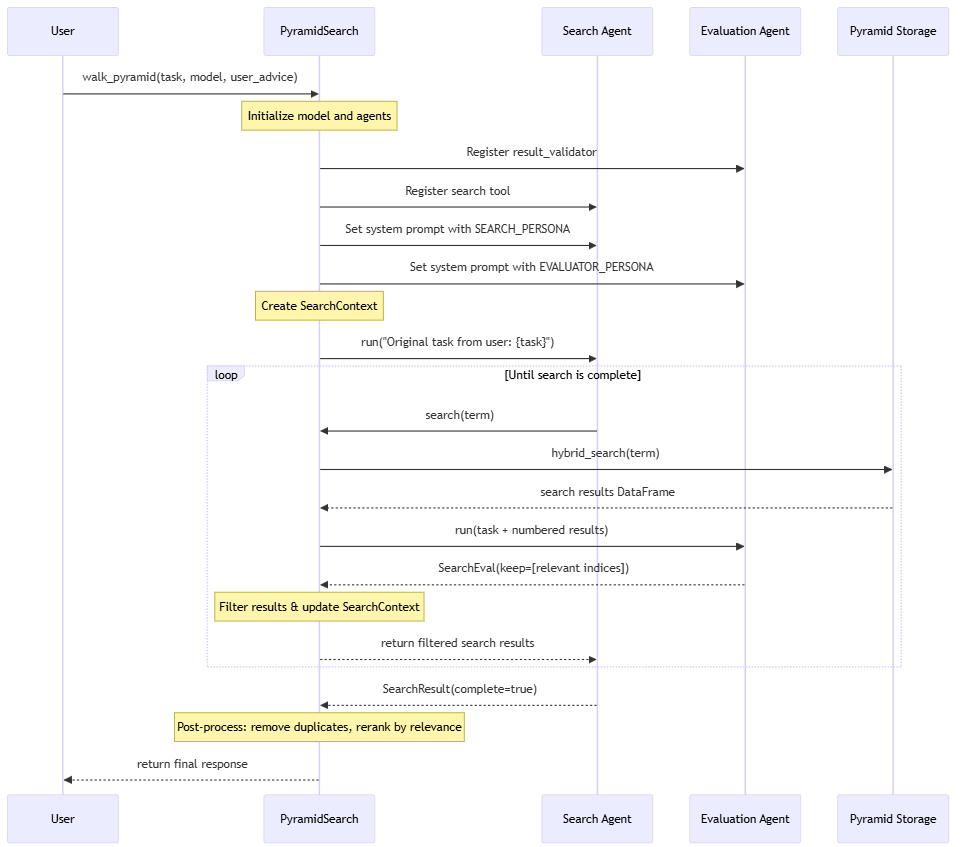
The good thing about the pyramid strategy is that info at any and all ranges of the pyramid can be utilized throughout inference. For our implementation, we used PydanticAI to create a search agent that takes within the consumer request, generates search phrases, explores concepts associated to the request, and retains monitor of data related to the request. As soon as the search agent determines there’s ample info to deal with the consumer request, the outcomes are re-ranked and despatched again to the LLM to generate a closing reply. Our implementation permits a search agent to traverse the data within the pyramid because it gathers particulars a few idea/search time period. That is much like strolling a data graph, however in a means that’s extra pure for the LLM since all the data within the pyramid is saved in pure language.
Relying on the use case, the Agent might entry info in any respect ranges of the pyramid or solely at particular ranges (e.g. solely retrieve info from the ideas). For our experiments, we didn’t retrieve uncooked page-level information since we wished to give attention to token effectivity and located the LLM-generated info for the insights, ideas, abstracts, and recollections was ample for finishing our duties. In concept, the Agent might even have entry to the web page information; this would offer extra alternatives for the agent to re-examine the unique doc textual content; nevertheless, it could additionally considerably improve the entire tokens used.
Here’s a high-level visualization of our Agentic strategy to responding to consumer requests:
Outcomes from the pyramid: Actual-world examples
To guage the effectiveness of our strategy, we examined it towards quite a lot of query classes, together with typical fact-finding questions and complicated cross-document analysis and evaluation duties.
Reality-finding (spear fishing):
These duties require figuring out particular info or details which are buried in a doc. These are the sorts of questions typical RAG options goal however usually require many searches and eat plenty of tokens to reply appropriately.
Instance process: “What was IBM’s complete income within the newest monetary reporting?”
Instance response utilizing pyramid strategy: “IBM’s complete income for the third quarter of 2024 was $14.968 billion [ibm-10q-q3-2024.pdf, pg. 4]
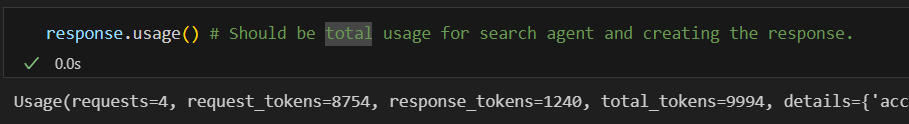
This result’s right (human-validated) and was generated utilizing solely 9,994 complete tokens, with 1,240 tokens within the generated closing response.
Advanced analysis and evaluation:
These duties contain researching and understanding a number of ideas to achieve a broader understanding of the paperwork and make inferences and knowledgeable assumptions based mostly on the gathered details.
Instance process: “Analyze the investments Microsoft and NVIDIA are making in AI and the way they’re positioning themselves available in the market. The report needs to be clearly formatted.”
Instance response:
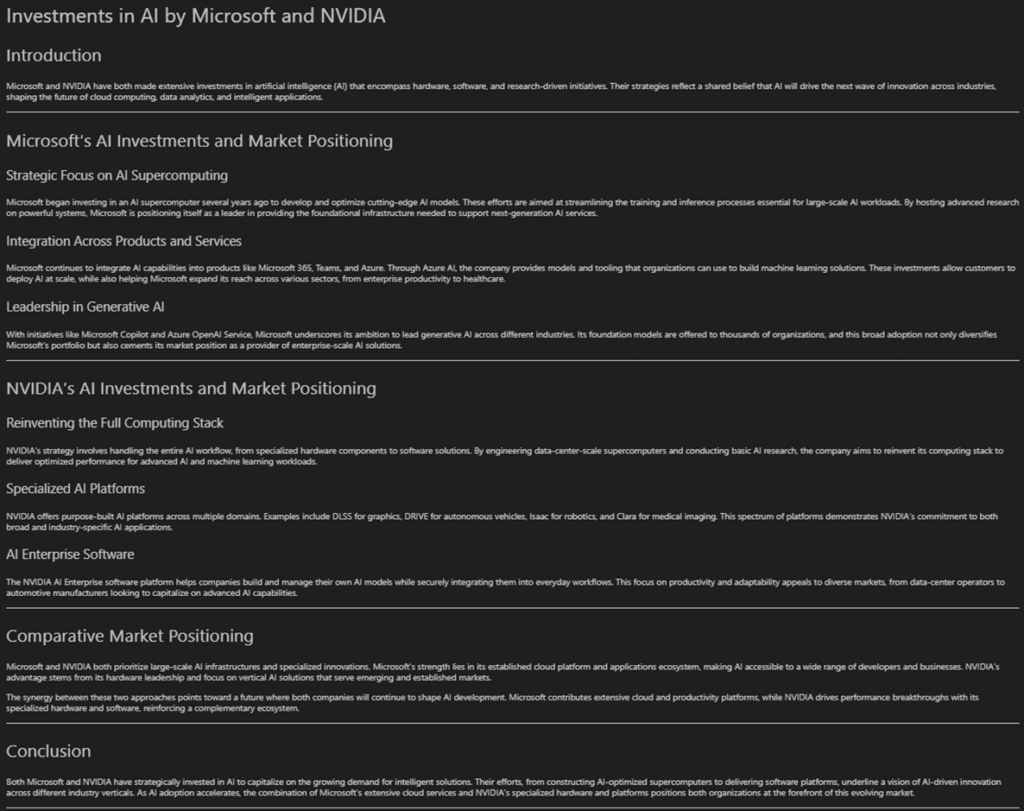
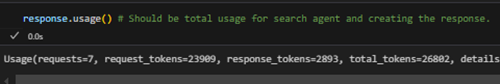
The result’s a complete report that executed rapidly and accommodates detailed details about every of the businesses. 26,802 complete tokens have been used to analysis and reply to the request with a major share of them used for the ultimate response (2,893 tokens or ~11%). These outcomes have been additionally reviewed by a human to confirm their validity.
Instance process: “Create a report on analyzing the dangers disclosed by the assorted monetary firms within the DOW. Point out which dangers are shared and distinctive.”
Instance response:
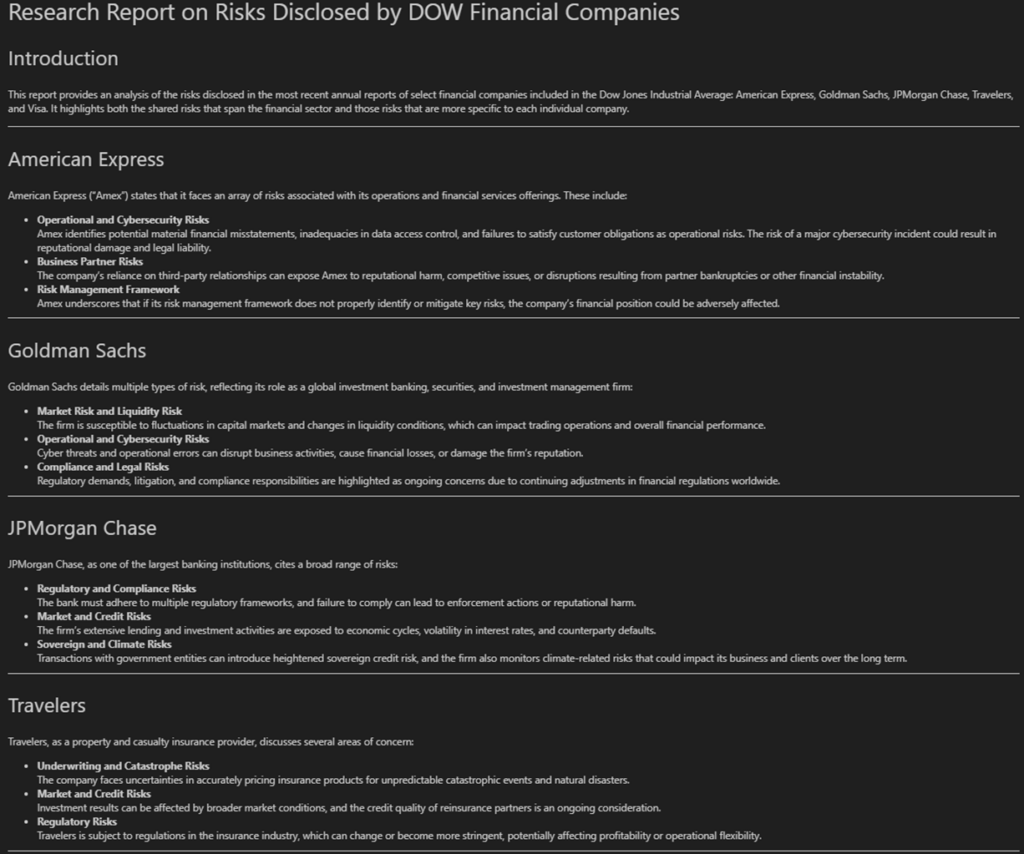
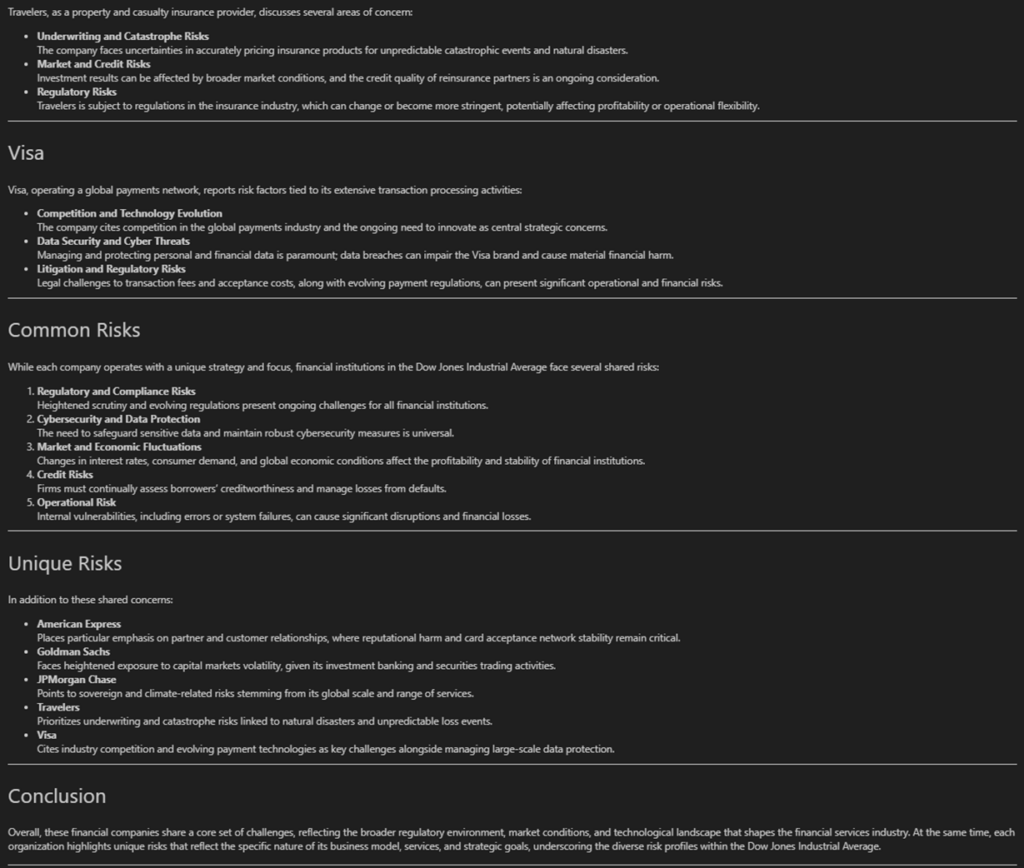
Equally, this process was accomplished in 42.7 seconds and used 31,685 complete tokens, with 3,116 tokens used to generate the ultimate report.
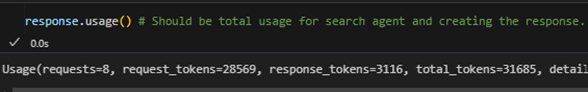
These outcomes for each fact-finding and complicated evaluation duties show that the pyramid strategy effectively creates detailed reviews with low latency utilizing a minimal quantity of tokens. The tokens used for the duties carry dense that means with little noise permitting for high-quality, thorough responses throughout duties.
Advantages of the pyramid: Why use it?
General, we discovered that our pyramid strategy supplied a major enhance in response high quality and general efficiency for high-value questions.
A few of the key advantages we noticed embody:
Diminished mannequin’s cognitive load: When the agent receives the consumer process, it retrieves pre-processed, distilled info relatively than the uncooked, inconsistently formatted, disparate doc chunks. This essentially improves the retrieval course of for the reason that mannequin doesn’t waste its cognitive capability on attempting to interrupt down the web page/chunk textual content for the primary time.
Superior desk processing: By breaking down desk info and storing it in concise however descriptive sentences, the pyramid strategy makes it simpler to retrieve related info at inference time by pure language queries. This was significantly necessary for our dataset since monetary reviews comprise plenty of important info in tables.
Improved response high quality to many sorts of requests: The pyramid allows extra complete context-aware responses to each exact, fact-finding questions and broad evaluation based mostly duties that contain many themes throughout quite a few paperwork.
Preservation of important context: Because the distillation course of identifies and retains monitor of key details, necessary info which may seem solely as soon as within the doc is less complicated to keep up. For instance, noting that each one tables are represented in tens of millions of {dollars} or in a selected forex. Conventional chunking strategies usually trigger any such info to slide by the cracks.
Optimized token utilization, reminiscence, and pace: By distilling info at ingestion time, we considerably cut back the variety of tokens required throughout inference, are in a position to maximize the worth of data put within the context window, and enhance reminiscence use.
Scalability: Many options battle to carry out as the dimensions of the doc dataset grows. This strategy supplies a way more environment friendly method to handle a big quantity of textual content by solely preserving important info. This additionally permits for a extra environment friendly use of the LLMs context window by solely sending it helpful, clear info.
Environment friendly idea exploration: The pyramid allows the agent to discover associated info much like navigating a data graph, however doesn’t require ever producing or sustaining relationships within the graph. The agent can use pure language solely and preserve monitor of necessary details associated to the ideas it’s exploring in a extremely token-efficient and fluid means.
Emergent dataset understanding: An surprising advantage of this strategy emerged throughout our testing. When asking questions like “what are you able to inform me about this dataset?” or “what sorts of questions can I ask?”, the system is ready to reply and recommend productive search matters as a result of it has a extra strong understanding of the dataset context by accessing larger ranges within the pyramid just like the abstracts and recollections.
Past the pyramid: Analysis challenges & future instructions
Challenges
Whereas the outcomes we’ve noticed when utilizing the pyramid search strategy have been nothing wanting wonderful, discovering methods to determine significant metrics to judge your complete system each at ingestion time and through info retrieval is difficult. Conventional RAG and Agent analysis frameworks usually fail to deal with nuanced questions and analytical responses the place many alternative responses are legitimate.
Our group plans to jot down a analysis paper on this strategy sooner or later, and we’re open to any ideas and suggestions from the group, particularly in relation to analysis metrics. Lots of the present datasets we discovered have been centered on evaluating RAG use circumstances inside one doc or exact info retrieval throughout a number of paperwork relatively than strong idea and theme evaluation throughout paperwork and domains.
The principle use circumstances we’re taken with relate to broader questions which are consultant of how companies truly need to work together with GenAI techniques. For instance, “inform me every thing I have to find out about buyer X” or “how do the behaviors of Buyer A and B differ? Which am I extra prone to have a profitable assembly with?”. Most of these questions require a deep understanding of data throughout many sources. The solutions to those questions sometimes require an individual to synthesize information from a number of areas of the enterprise and assume critically about it. Consequently, the solutions to those questions are hardly ever written or saved wherever which makes it unimaginable to easily retailer and retrieve them by a vector index in a typical RAG course of.
One other consideration is that many real-world use circumstances contain dynamic datasets the place paperwork are persistently being added, edited, and deleted. This makes it troublesome to judge and monitor what a “right” response is for the reason that reply will evolve because the accessible info adjustments.
Future instructions
Sooner or later, we consider that the pyramid strategy can deal with a few of these challenges by enabling simpler processing of dense paperwork and storing realized info as recollections. Nevertheless, monitoring and evaluating the validity of the recollections over time might be important to the system’s general success and stays a key focus space for our ongoing work.
When making use of this strategy to organizational information, the pyramid course of may be used to establish and assess discrepancies throughout areas of the enterprise. For instance, importing all of an organization’s gross sales pitch decks might floor the place sure services or products are being positioned inconsistently. It may be used to check insights extracted from varied line of enterprise information to assist perceive if and the place groups have developed conflicting understandings of matters or completely different priorities. This software goes past pure info retrieval use circumstances and would permit the pyramid to function an organizational alignment instrument that helps establish divergences in messaging, terminology, and general communication.
Conclusion: Key takeaways and why the pyramid strategy issues
The data distillation pyramid strategy is critical as a result of it leverages the total energy of the LLM at each ingestion and retrieval time. Our strategy permits you to retailer dense info in fewer tokens which has the additional advantage of decreasing noise within the dataset at inference. Our strategy additionally runs in a short time and is extremely token environment friendly, we’re in a position to generate responses inside seconds, discover doubtlessly tons of of searches, and on common use <40K tokens for your complete search, retrieval, and response technology course of (this contains all of the search iterations!).
We discover that the LLM is a lot better at writing atomic insights as sentences and that these insights successfully distill info from each text-based and tabular information. This distilled info written in pure language may be very straightforward for the LLM to know and navigate at inference because it doesn’t need to expend pointless vitality reasoning about and breaking down doc formatting or filtering by noise.
The flexibility to retrieve and mixture info at any degree of the pyramid additionally supplies important flexibility to deal with quite a lot of question sorts. This strategy presents promising efficiency for giant datasets and allows high-value use circumstances that require nuanced info retrieval and evaluation.
Observe: The opinions expressed on this article are solely my very own and don’t essentially mirror the views or insurance policies of my employer.
Excited by discussing additional or collaborating? Attain out on LinkedIn!
[ad_2]
Source link


